10 AI Agent Components Every Developer Should Understand
AI agent components explained for ops leads who need systems that run without becoming the coordination layer themselves.
 Skydive 19 min read
Table of contents
Knowing every AI agent component is not the same as knowing how they break. Here is what the standard checklist leaves out, and why it keeps costing teams in production.
Knowing the parts list feels like enough, and most heads of operations assume that if they understand each AI agent component individually, they can compose them into any multi-agent system they need. You can name memory, planning, tool use, reasoning engine, orchestration layer. You can sketch the diagram on a whiteboard. And then you try to build something that actually runs across your team’s tools and hands off work without a human stitching every step together, and the diagram stops helping. See our AI Employees for how this works in practice.
That gap is an architecture gap, and it costs more than a broken demo. According to industry research, between 70 and 95 percent of AI agent projects fail in production environments. The component knowledge exists. The tutorials were followed. The demos worked. What collapsed was the architecture underneath, because every standard checklist was designed to explain a single agent in isolation, not to survive contact with real workload conditions.
The checklist teaches you what each part does when nothing else is competing for it. The problem is that production is never sequential. A second agent needs the same memory store. Two tasks collide in the planner. A tool call fails mid-handoff. None of that appears in the tutorial, because the tutorial never had a second agent in the frame.
The problem is that production is never sequential.
Key takeaways
- AI agent components don’t behave the same in isolation as they do inside a multi-agent system, memory, planning, and tool use each run a second job the moment a second agent depends on them.
- Most teams can name every component and still spend months before a single agent handles real operational work; 88% of AI agents never reach production.
- When agents are built as isolated tools, humans become the coordination layer, absorbing the handoffs, context gaps, and judgment calls the architecture never defined.
- Work fails at the seam between agents, not at the component level: the second agent reaches for memory the first never shared, or calls a tool the registry never exposed to it.
- Getting AI agent architecture wrong isn’t just a technical cost, it’s an organizational one, as coordination overhead shifts back onto the people the agents were supposed to free up.
- Skydive closes that gap by shipping AI teammates whose components, memory, tool access, orchestration, are already wired to work together across Slack, email, iMessage, and web chat, so the infrastructure problem is solved before your team writes a single prompt.
The Hidden Cost of Getting AI Agent Architecture Wrong
Most teams building with AI agents focus on getting individual components to work, then discover too late that the real failure point is everything in between them. The architecture decisions made early, often skipped entirely in the rush to ship, determine whether coordination overhead stays inside the system or gets pushed onto the people operating it. This section breaks down why that gap exists and what it costs when the underlying structure isn’t there to support agents working across boundaries.
When Agents Are Built as Isolated Tools, Humans Become the Coordination Layer
The common assumption is that if you understand each AI agent component individually, you can compose them into any multi-agent system you need. Yet according to a RAND Corporation report on the root causes of AI project failure, more than 80 percent of AI projects fail, twice the rate of traditional IT projects, and broader market trends covered by Fortune found that the vast majority of generative AI pilots at companies are failing. The pattern behind both numbers is consistent: single-tool agents perform well in controlled conditions, then stall the moment work crosses a boundary they were never designed to cross.
“Most beginners fail because they skip foundational systems engineering and jump straight to using no-code wrappers or prompting, resulting in unreliable agents that cannot solve real business problems.”
A significant part of why this happens is foundational. Beginners building on AI, and even experienced teams under delivery pressure, tend to skip systems engineering entirely, reaching instead for no-code wrappers or prompt-chaining shortcuts. The result is agents that look capable in a demo and collapse in production, because there is no architecture underneath them that handles handoffs, ownership, or state across steps.
The coordination overhead doesn’t disappear. It relocates, landing squarely on the operations team. The practical version of this is an ops lead who becomes the engineer, manually copying context between three Slack threads because no shared memory exists between the agents involved.
Skydive is built multi-teammate by default, which means coordination is an architectural decision made at the platform level, not a problem delegated to your team. Each teammate operates in its own per-teammate sandbox with browser access, granular permissions define who owns what, and the whole system is designed to coordinate complex, multi-step workflows without losing track of ownership at each stage, so your team can stay focused on high-impact work instead of status updates.
The Memory Gap - Why Judgment Trapped in One Agent’s Context Doesn’t Compound
When an agent’s memory resets at the end of a session, every judgment call it made resets too. The next agent in the workflow starts cold. Judgment trapped in a single context window evaporates rather than compounding across your team.
This is the default failure mode when teams bolt single-purpose agents together without a shared memory layer, and it is exactly what makes the high pilot failure rates that most adopting teams report so predictable. Teams measure the agent in isolation, declare success, and then discover in production that institutional context, the judgment accumulated across dozens of sessions, simply does not carry forward.
Skydive’s architecture addresses this directly through built-in memory and persistence. Context carries forward across sessions rather than resetting, so the decisions and context an AI teammate builds up over time remain available to the next step in a workflow and to the wider team. Combined with multi-channel access and granular team collaboration controls, this means operations teams avoid the manual re-briefing overhead that per-session state creates, the kind of overhead that quietly consumes the hours that were supposed to be reclaimed by adopting AI in the first place.
Single-Chat AI Fails the Moment Work Crosses Agent Boundaries
The same RAND Corporation research that documented the failure rate of AI projects points to a structural cause: systems designed without the connective tissue that real workflows require. Single-chat AI is the clearest example. It handles one thread, in one context, for one user, and the moment a task requires a handoff to another agent, another channel, or another tool, the chain breaks.
Beginners in particular feel this acutely. Without foundational systems engineering underneath an agent deployment, there is no mechanism for a teammate to pass state, trigger a downstream action, or even know that another agent exists. The human fills that gap, copy-pasting outputs, re-entering context, bridging tools that were never designed to talk to each other.
Skydive removes that gap at the architecture level. Pre-built teammate templates give teams a starting point that is already wired for multi-step execution. Scheduled runs mean workflows continue without a human triggering each step. MCP (Model Context Protocol) support and built-in tools and capabilities mean teammates can connect to the systems your work already lives in, rather than existing as a parallel layer someone has to manually sync. The result is a platform where complex, multi-step workflows run with clear ownership at each stage, and where the back-and-forth communication overhead that stalls teams is engineered out rather than managed around.
The 10 AI Agent Components Every Developer Should Understand
Build a single agent and the architecture feels solved. Wire two agents together and you discover the components you thought you understood are running a second job you never defined.
That gap is where production failures live. The 10 components below are each real, each necessary, and each carries a behavior in isolation that changes the moment it must share state, hand off context, or persist judgment across sessions. Understanding both modes is the difference between a working demo and working infrastructure.
The failure pattern is consistent: developers write prompts, add tools, and build a working demo, then hit a wall when agents interact, because the gap between “I understand this component” and “I understand why my system failed” is a coordination gap. That illusion of control is the sharpest risk in early-stage agent development, and it is the reason component mastery must extend to coordination behavior, not just isolated function.
1. Perception Layer - The Multi-Modal Sensory Gateway
The perception layer is how an agent reads the world: text, files, images, structured data, API responses, calendar events. In a single agent, this is a straightforward intake problem. In a multi-agent system, it becomes a routing problem. When one agent ingests a PDF contract and a second agent needs to act on specific clauses, the perception layer must be designed to pass structured, queryable outputs, not raw text blobs. Teams that treat perception as a simple input step almost always hit this wall when they try to coordinate agents across document-heavy workflows.
2. The Large Language Model Core - Reasoning Engine at the Center
The LLM core is the reasoning engine that interprets inputs, generates plans, and produces outputs. Its quality ceiling is set by the model you choose; its failure floor is set by how well you ground it. Industry data consistently shows that ungrounded LLMs in production agent pipelines produce hallucinated outputs at rates that make autonomous action unreliable without retrieval mechanisms. In multi-agent architectures, industry research notes that planning and reasoning are distributed across agents rather than residing in a single component, which means a weak LLM core in one agent can corrupt the reasoning chain for every downstream agent it feeds.
3. Short-Term Memory - In-Context Working State Management
Short-term memory is the context window: everything the agent holds in active attention during a single session. It is fast, immediately accessible, and finite. The tradeoff is hard.
Context windows have token limits, and once a long-running task exceeds that limit, earlier context is truncated. Developers who have watched an agent repeat a research step it completed 40 minutes earlier, or re-ask a question already answered three exchanges back, have hit this ceiling. The fix in a single-agent setup is aggressive summarization; the fix in a multi-agent setup is a shared external memory store that no single context window can exhaust.
4. Long-Term Memory - Persistent Vector Store for Cross-Session Recall
Long-term memory is how an agent remembers across sessions: vector databases that store embeddings of past interactions, decisions, and retrieved documents. A single agent uses this to avoid repeating itself across days. Two agents sharing a vector store unlock something more significant: the first agent’s research is immediately available to the second without a human re-briefing it. That compounding effect separates agents that feel like persistent teammates from agents that feel like stateless tools you have to prime from scratch every morning. Skydive’s memory and persistence layer is built into the platform so that context accumulated by one teammate carries forward across sessions and across the team, no manual re-briefing, no lost state between handoffs.
5. Planning Module - Goal Decomposition and Task Sequencing
The planning module breaks a high-level goal into ordered, executable steps. In a single agent, planning is linear: the agent sequences its own actions. In a multi-agent architecture, planning becomes distributed.
A lead orchestrator decomposes a task and delegates subtasks to specialist agents, which means the planning module must produce outputs that other agents can interpret and act on without ambiguity. Vague plans that a human would intuit correctly become coordination failures when passed between agents. The planning layer is where imprecision compounds fastest at scale.
This is precisely why Skydive is designed to coordinate complex, multi-step workflows without losing track of who owns what at each stage, giving every teammate a clear, predictable process so no one is walking blindly into their next task or handoff.
6. Tool Calling Interface - Structured API and Function Execution Layer
The tool calling interface is how agents take action in external systems. A single agent with five tools is manageable. The tradeoff surfaces quickly as the registry grows. Specifically, the tool calling interface supports:
- Running API calls
- Querying databases
- Sending messages
- Writing files
- Executing other structured function calls against external systems
Research on tool selection accuracy in agent benchmarks shows that agents increasingly misroute calls as the number of available tools expands, a pattern that developers who have built large tool registries know firsthand. In a multi-agent system, tool registries must be scoped deliberately per agent rather than shared as a single flat list, or misrouting becomes a compounding source of silent errors. Skydive addresses this with per-teammate sandboxes, granular permissions, and MCP (Model Context Protocol) support, so each teammate operates against a scoped, controlled tool surface rather than an undifferentiated flat registry.
7. Execution Engine - Parallel Action Dispatch and Side-Effect Management
The execution engine handles the actual dispatch of actions: running tool calls, managing parallel threads, and handling the consequences of actions that cannot be undone. Parallel execution is where agent architectures earn their speed advantage and incur their most serious operational risk. An agent that fires three API calls simultaneously, one of which triggers an irreversible database write, is not a hypothetical; it is a pattern that surfaces in production environments where execution was designed for speed without guardrails for side-effect management.
Parallel action dispatch requires explicit rollback logic and idempotency checks as first-class design constraints. Skydive’s granular permissions model and per-teammate sandboxes provide the isolation layer that prevents one agent’s execution side-effects from propagating silently across the rest of the team.
8. Knowledge Base - Structured Domain Context and Retrieval-Augmented Generation
The knowledge base is the agent’s domain library: product documentation, policy files, historical decisions, structured reference data. Retrieval-augmented generation (RAG) pulls from this store at inference time to ground the LLM core in facts rather than parametric memory. Without it, the LLM defaults to what it learned during training, which is often outdated or too general for the specific domain the agent is operating in.
In a multi-agent system, a shared knowledge base means every agent in the team operates from the same factual foundation, which is the prerequisite for consistent, coordinated judgment across a workflow. Skydive’s built-in tools and capabilities are designed to support this shared-foundation model, so the team of AI teammates handles work across every function without each agent starting from a different, inconsistent base of domain knowledge.
9. Feedback and Learning Loop - Adaptive Improvement from Human and Environment Signals
The feedback loop is how an agent improves over time: human corrections, environment signals, and task success and failure rates fed back into the system to refine future behavior. Most single-agent implementations treat this as optional, something to add after the core is stable. That instinct is understandable and almost always wrong. Without a feedback mechanism, an agent that makes a systematic error will repeat it indefinitely.
In a multi-agent setup, feedback must be routed to the right agent rather than broadcast indiscriminately, or corrections applied to one agent will silently degrade the calibration of another. Skydive’s multi-teammate architecture is built with coordination as a default, which means the feedback surface maps to individual teammates through granular permissions and team collaboration controls rather than being applied as an undifferentiated broadcast across the whole system. Corrections land where they belong, and teams stay focused on high-impact work instead of manually tracking which agent needs which correction.
10. Multi-Agent Orchestration Protocol - Coordination Layer for Agent-to-Agent Collaboration
Orchestration is the coordination layer that governs how agents communicate, delegate, and synchronize. As noted in industry research, multi-agent systems require shared infrastructure, including shared tool registries, shared memory, and coordinated context handoff, that cannot be assembled simply by composing individually understood components, because the coordination layer itself introduces emergent complexity. The latency and throughput costs of agent-to-agent message passing are real and measurable at scale. Orchestration is the component where most teams discover that wiring agents together is an architecture problem, not a wiring problem.
Skydive is built multi-teammate by default, which means the orchestration layer, multi-channel access, scheduled runs, pre-built teammate templates, and coordinated context handoff across teammates, is not assembled after the fact. It is the starting point. Teams that need to handle work across every function without adding headcount have the coordination infrastructure in place before the first agent goes to production, not after the first production incident reveals it was missing.
The assigned original insight from the evidence base is worth stating plainly here: component mastery creates a false confidence ceiling. Developers who can name and explain every component above are statistically no better protected against production failure than those who cannot, because the failure modes that surface in production are coordination-surface failures. They only appear when components interact across agents. Understanding what each component does in isolation is the prerequisite. It is not the protection.
Knowing what each component does in isolation is the prerequisite, but it is the floor. The next section shows what happens when these 10 components stop living inside a single agent and start functioning as shared infrastructure across an entire agent team, where the architecture either compounds your team’s judgment or collapses under its own coordination weight.
Related Reading
- Multi Agent Orchestration Explained: What It Is and How It Works
- The Complete Guide to AI Agent Infrastructure & Components
- Make vs n8n: Which Automation Tool Wins in 2026?
- 13 Best Lindy AI Alternatives for Smarter Automation 2026
- Gumloop vs n8n: Which Automation Tool Should You Choose?
- 13 Best AI Agent Builders in 2026
How AI Agent Components Become Infrastructure When Agents Work Together
Work doesn’t fail at the component level. It fails at the seam between agents, when the second agent reaches for memory the first agent never shared, or calls a tool the registry never exposed to it. That seam is where most AI agent architectures quietly collapse, and it’s almost never visible until real workload hits.
From Anatomy to Infrastructure - Why the Shift in Mental Model Changes Everything
Knowing what memory does inside a single agent is useful. Knowing how memory behaves when two agents write to it simultaneously, in the middle of a live workflow, is the actual design problem. As industry research has noted, “understanding each AI agent component individually is insufficient for composing multi-agent systems; the shift from ‘agent anatomy’ to ‘agent infrastructure’ is required.” Components that perform cleanly in isolation often become bottlenecks the moment a second agent needs to share them. This is an architectural problem.
A Concrete Multi-Agent Workflow - Perception to Output Across Two Agents in Real Time
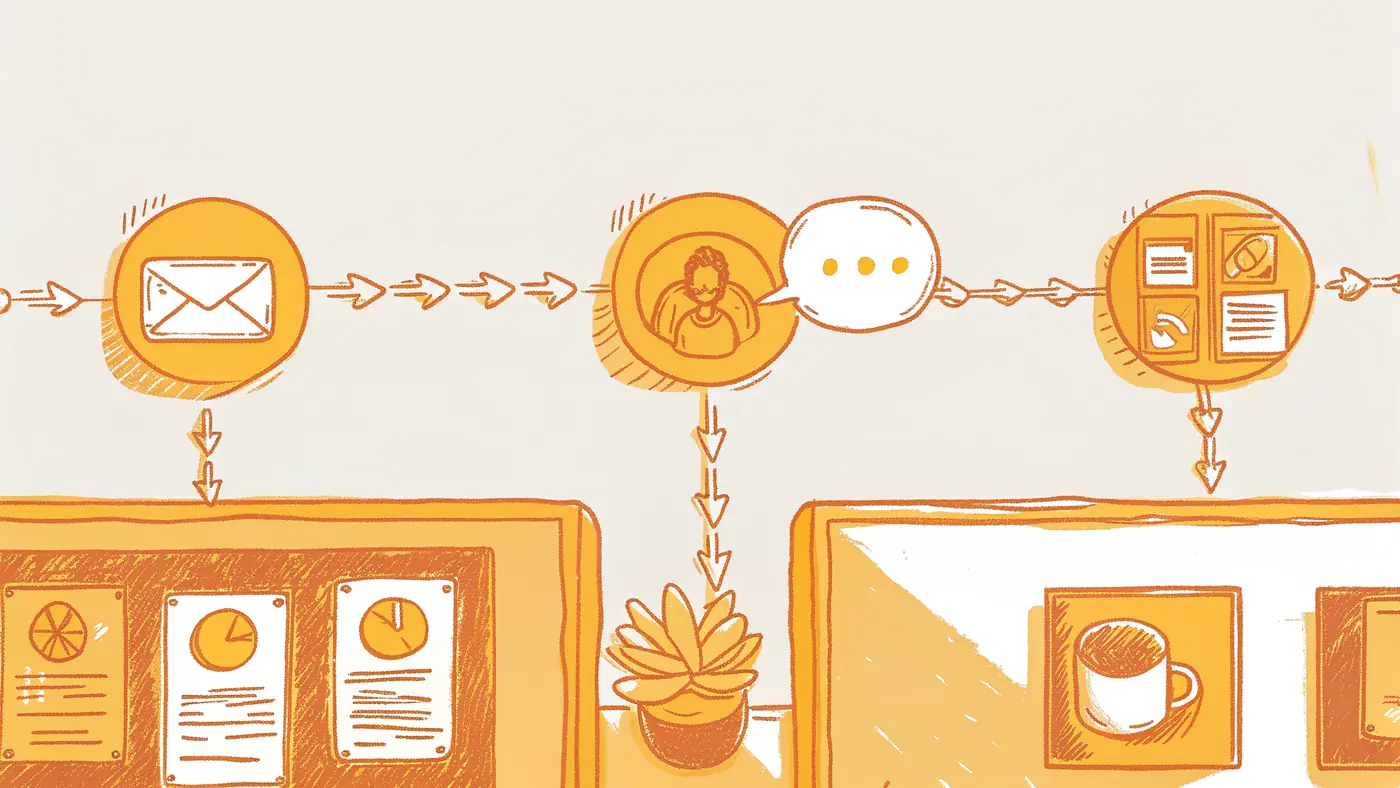
Consider a three-agent sequence a Head of Operations would recognize. Agent 1 ingests an inbound vendor email and routes it through the orchestration layer. Agent 2 pulls the relevant contract terms via tool use. Agent 3 drafts a reply and posts it to Slack. No human handoff. The catch: this only works if all three agents draw from the same memory layer and the same tool registry. If Agent 2 stores its contract findings in a local context window that Agent 3 cannot read, the chain breaks. The output arrives blank, or wrong, or not at all.
Next steps
If your agents work in isolation but break the moment work crosses a boundary, the path forward starts with treating coordination as a first-class architectural decision, not a byproduct of composing capable individual components.
Component mastery creates a false confidence ceiling: developers who can name every layer of an AI agent architecture are statistically no better protected against production failure than those who cannot, because the failures happen at the seam between agents, not inside any single component. And when coordination infrastructure is missing, human workers silently absorb the state synchronization and context translation work the architecture was never designed to handle, which means the cost of a poorly coordinated agent system is not a broken demo but an invisible tax on your operations team. Together, those two realities point to one logical next step: starting from components that are already wired to coordinate, rather than assembling that coordination layer yourself under production pressure.
Start with AI Employees from Skydive, where memory, tool registries, orchestration, and permissions arrive pre-integrated across a multi-teammate architecture. From there, your team runs complex, multi-step workflows without becoming the engineer that holds them together.
Frequently Asked Questions
What’s the difference between short-term and long-term memory in an AI agent?
Short-term memory is the context window, everything the agent holds in active attention during a single session, and it is finite, meaning earlier context gets truncated when a long-running task exceeds its token limit. Long-term memory uses vector databases to store embeddings of past interactions, decisions, and retrieved documents across sessions, so an agent can recall prior work without being re-briefed from scratch every time.
Why do AI agent demos work fine but then fall apart in production?
Demos almost always test a single agent in isolation, where memory, planning, and tool use have nothing competing with them. In production, a second agent may need the same memory store, two tasks can collide in the planner, or a tool call fails mid-handoff, none of which appear in a single-agent tutorial. The failure is an architecture gap, not a knowledge gap.
How does retrieval-augmented generation (RAG) help ground an AI agent?
RAG pulls from a knowledge base, product documentation, policy files, historical decisions, structured reference data, at inference time so the LLM core reasons from current, domain-specific facts rather than relying on what it learned during training. Without it, the model defaults to parametric memory that is often outdated or too general for the specific domain the agent is operating in.
Why does the feedback loop matter, and what goes wrong without one?
Without a feedback mechanism, an agent that makes a systematic error will repeat it indefinitely. In a multi-agent setup the stakes are higher: feedback must be routed to the specific agent that needs it, because corrections applied indiscriminately can silently degrade the calibration of agents that did not need correcting.
What does orchestration actually do in a multi-agent system?
Orchestration is the coordination layer that governs how agents communicate, delegate, and synchronize with one another. A lead orchestrator decomposes a high-level goal and delegates subtasks to specialist agents, which means the planning outputs must be precise enough for other agents to act on without ambiguity, vague plans that a human would intuit correctly become coordination failures when passed between agents.