What Are AI Agent Capabilities and Why They Matter
AI agent capabilities determine if your rollout compounds or stalls. Ops leaders, learn what true agency means before your next pilot fails.
 Skydive 25 min read
Table of contents
Most AI rollouts stall because teams deploy chatbots expecting agents. Six architectural capabilities separate a tool that waits from one that owns the work.
Most AI rollouts stall not because the technology is immature, but because teams are deploying chatbots while expecting agents. Perception, reasoning, and action are the three non-negotiable components of a true AI agent:
- Perception: The agent must read its environment.
- Reasoning: The agent must pursue a goal, not just answer a question.
- Action: The agent must execute across tools autonomously.
Strip any one of them out, and what remains is a tool that waits. The common assumption is that AI agents are sophisticated chatbots: useful for Q&A and summaries, but not capable of owning tasks end-to-end or handing work off across tools without a human in the loop. That assumption is understandable, but it is also the reason most AI rollouts stall before they deliver anything meaningful. See our AI Employees for how this works in practice.
“Users struggle to distinguish between a basic chatbot interaction (asking the field a question) and a true AI agent that takes autonomous action, directly reflecting the ‘chatbot definition’ confusion the article addresses.”
Most ops leaders have been burned by the same experience. They adopt an “AI agent,” spend a week configuring it, demo it to their team, and then watch it collect dust because it still needs them to type every instruction, interpret every output, and manually move results from one tool to the next. That gap, between what was promised and what actually showed up, is a definitional one. Understanding it is the difference between an AI rollout that compounds and one that stalls permanently at the pilot stage.
A traditional software tool executes a command. An agent pursues an outcome, deciding on its own which steps to take, in which order, using which resources. Most AI assistants, including widely used conversational tools, are reactive: you prompt, they respond, and no work is completed in your absence. The confusion is operationally costly. Cited by Fortune in August 2025, 95% of generative AI pilots at companies are failing. Misaligned expectations about what the tool category can actually do is a documented root cause, a pattern that holds broadly across the market.
95% of generative AI pilots are failing
The “goal-directed” part is what separates agents from everything that came before. Teams deploy conversational AI expecting autonomous task ownership and receive reactive Q&A instead. That gap is a definitional one. An agent reasons about which steps to take, in which order, and using which resources, without a human closing the loop between each one. What crosses the line into true agency is tool use plus autonomous sequencing.
A Head of Ops who asks an AI to research a vendor, compile a summary, and book a meeting sees the distinction immediately. A chat tool answers the first question and stops. Strip out autonomous action, and what remains is a tool that waits, useful for Q&A, but not capable of owning tasks end-to-end or handing work off across tools without a human in the loop.
Key takeaways
- An AI agent without all three components, perception, reasoning, and action, is not an agent. It’s a tool that waits for a human to close the loop.
- The architecture underneath an agent is what determines whether it owns work end-to-end or hands the question back to you. Most deployed agents do the latter.
- Six core capabilities separate genuine autonomy from the appearance of it, and most single-agent deployments are missing at least two.
- Deploying the wrong agent type doesn’t give you automation. It gives you something that looks like automation but still requires a human between every step.
- The hours don’t disappear inside tasks, they disappear in the seams between systems. That’s where AI agent workflow automation earns its keep.
- The risks of AI agents are as real as the benefits. A system that produces garbage confidently is worse than no system at all.
- Skydive closes that gap by putting AI teammates directly inside the tools teams already use, Slack, email, iMessage, web chat, so agents hand work off across systems without pulling humans back into the loop.
How AI Agents Work - The Architecture Behind Autonomous Action
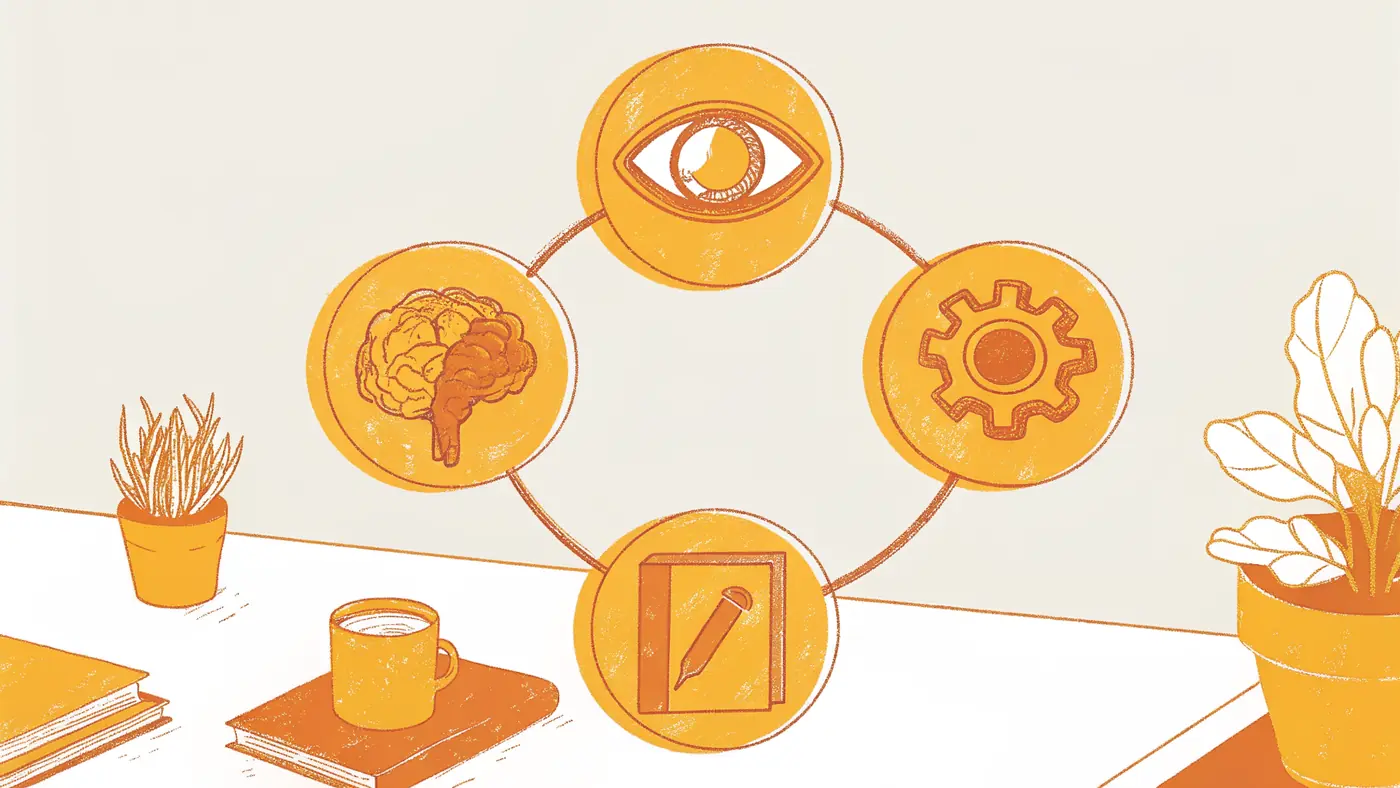
The architecture underneath an agent is what closes that gap, or exposes it. Think of an LLM as the most capable analyst you’ve ever hired, one who can reason through anything you put in front of them, but who has no eyes, no hands, and no memory of yesterday. That’s the gap most ops leaders hit when they deploy a base model expecting real work to get done. The model reasons fine. Nothing actually moves.
The LLM - Cognitive Engine Without a Body
An LLM alone is a brain in a jar. It processes whatever text you hand it and generates a response. Without additional architectural layers, it cannot observe what’s happening in your systems, retain what happened last Tuesday, or touch a single external tool. As Menlo Ventures noted in their 2025 State of Generative AI in the Enterprise report, the agentic layer wraps around LLMs to give them perception, memory, and tool use. Remove any one of those layers and you have a very articulate chatbot.
Perception - How Agents Build Context
Agents process inputs from their surroundings, including text, structured data, and API signals, to build a dynamic understanding of their operating context. NLP handles unstructured language for text understanding: a Slack message, an email thread, a customer complaint. Structured inputs come from APIs, database queries, and event triggers. Together, these form the agent’s situational awareness. An agent receiving a Slack message needs to parse intent, identify the relevant system, and decide what to do next, all before the LLM reasoning loop even begins. Perception is what makes that possible.
Memory and State - No Starting From Zero
Short-term memory holds context within a session. Long-term memory, typically built on retrieval-augmented generation, lets agents carry prior decisions, preferences, and outcomes across sessions. Without persistent memory, every interaction resets the agent to zero, it cannot learn from past runs, adapt to user preferences, or maintain continuity across a multi-step workflow. Memory is what separates a stateless chatbot from an agent that compounds value over time.
The 6 Core AI Agent Capabilities That Make Autonomous Work Possible
Six core capabilities answer that question. Strip away the model quality, the prompt engineering, the clever system instructions, and what remains determines whether your AI actually owns the work or hands the question back to you.
The honest answer, for most teams, is the second one. A single capability in isolation, no matter how sophisticated, cannot close a loop that requires six things working together. According to METR’s March benchmarking research, AI agents are now evaluated specifically on their ability to complete long, multi-step tasks without human intervention at each step, a standard that is categorically different from answering questions or summarizing documents. That distinction matters because it names the exact gap between what most teams have deployed and what autonomous work actually requires.
There is a second, harder gap. The organizational mandate is clear: deploy AI agents or fall behind. But building enterprise-grade agentic workflows that actually hold together in production is a different problem entirely. Teams that have felt that friction are not behind the curve; they have simply discovered that the directive and the execution require different things. The six capabilities below are what the execution actually requires.
The six capabilities below are the architectural conditions that separate a tool that waits for instructions from one that owns a workflow end to end. Remove any one of them and the agent stalls the moment conditions deviate from the expected path, which is precisely when you needed it most.
The six capabilities below are not a feature list. They are the architectural conditions that separate a tool that waits for instructions from one that owns a workflow end to end.
1. Goal-Directed Reasoning - Planning Multi-Step Tasks Without Human Prompting
Autonomous decision-making in AI agents means the agent evaluates a situation, weighs available options, and selects a course of action toward a defined goal without requiring a human to approve each step. In practice, this looks like an agent receiving a high-level objective, breaking it into ordered sub-tasks, and adapting its plan when an obstacle surfaces mid-execution.
This is where Skydive’s multi-teammate architecture earns its keep. Rather than routing every sub-task back through a single model, Skydive coordinates a team of specialized teammates through complex, multi-step workflows, tracking who owns what at each stage so the work keeps moving without a human acting as the router. For leaders who need their leverage to be persistent rather than session-dependent, that coordination layer is the difference between a capable tool and a genuine force multiplier.
The honest tradeoff: goal-directed reasoning is only as reliable as the goal specification. Vague objectives produce wandering execution chains, so the quality of the initial instruction still shapes the output ceiling.
2. Tool Calling - Connecting Agents to External APIs and Live Systems
Agents that can only reason internally are thinking in a sealed room. Tool calling is what lets an agent reach into a CRM, trigger an API, query a database, or push a record into a downstream system without a human acting as the connector. This is where autonomous work becomes real: an agent managing a vendor evaluation can pull live pricing, log findings, and draft a comparison, all in one uninterrupted sequence.
Skydive ships with built-in tools and capabilities and supports Model Context Protocol (MCP), which means teammates can connect to external systems through a standardized interface rather than requiring custom integration work for each new tool. Each teammate also runs inside its own per-teammate sandbox with browser access, so tool-calling happens in an isolated environment, a deliberate architecture choice that matters more than it might first appear.
METR’s research into long-task completion documented agents executing vast sequences of real-world actions in unsandboxed evaluation conditions, an illustration of how quickly unrestricted tool access scales beyond what teams intended to permit. Skydive’s per-teammate sandboxes and granular permissions are the containment layer that lets teams handle work spanning multiple tools without becoming the engineer managing every connection and every boundary.
The practical limitation is parameter reliability. Developer teams consistently report tool calls failing when agents hallucinate required fields or pass arguments in the wrong sequence, particularly in production environments where API schemas are complex. Robust agent architectures build validation layers into the tool-calling step precisely because this failure mode is predictable.
3. Long-Term Memory - Retaining Context Across Sessions and Extended Workflows
Short-term context is why most agents feel useful in a single conversation and frustrating across a week. Long-term memory, typically implemented through retrieval-augmented generation (RAG) for knowledge management, allows an agent to surface relevant past interactions, user preferences, and prior decisions when they become relevant again. A content pipeline agent that remembers which topics were covered last month and avoids repeating them is not a clever trick; it is memory doing the work that previously required a human to maintain a running document.
Skydive builds memory and persistence into the platform by default, not as an optional add-on. Teammates retain context across sessions, which means the CEO’s leverage does not reset at the end of each conversation, and decisions made in one workflow are available when a related workflow picks up days later. Scheduled runs extend this further: teammates can execute recurring workflows on a defined cadence, carrying prior context forward rather than starting cold each time.
The limitation worth naming: retrieval-backed memory is only as accurate as the retrieval index. Poorly structured knowledge bases return irrelevant chunks, and the agent confidently incorporates them. Memory quality scales with indexing discipline, not just model capability.
4. Multimodal Perception - Processing Text, Images, Audio, and Structured Data Together
AI agent capabilities expand significantly when the agent can read a PDF, interpret a Slack message, and parse a spreadsheet in the same reasoning pass. For operations leaders in healthcare, finance, or any field where information arrives in mixed formats, this capability is the difference between an agent that handles real work and one that handles clean, pre-processed inputs. Skydive’s multi-channel access means teammates can receive and act on inputs across the surfaces where work actually lives, rather than requiring teams to funnel everything through a single interface.
5. Self-Evaluation and Reflection - Detecting Errors and Correcting Outputs Autonomously
An agent that cannot check its own work will propagate errors silently through every downstream step. Self-evaluation gives an agent the ability to review its own output against the original goal, flag inconsistencies, and revise before passing the result forward. This is the capability that makes autonomous chains trustworthy rather than just fast.
As METR’s benchmarking methodology makes clear, the benchmark for autonomous agents is task completion without human intervention at each step, which means the agent’s ability to catch and correct its own errors is a prerequisite for meeting that standard at all. Tools that don’t stick with teams almost always fail here: they complete the easy, well-formed tasks and return the ambiguous or error-prone ones to the human, quietly reversing the leverage the team expected to gain.
The cost is real: reflection adds inference cycles, which increases latency and compute overhead. That tradeoff is worth accepting for high-stakes outputs where a silent error is more expensive than a slower response.
Types of AI Agents: and Which Capability Profile Matches Your Work
Choosing an AI agent type is not a configuration decision. It is the adoption decision. Deploy the wrong profile and you have not automated your work; you have built something that looks like automation but still requires a human to close every loop between steps.
The fault line sits between two structural realities. Reactive agents respond to triggers but carry no memory of what came before. Deliberative agents plan across steps but take time to reason. Multi-agent systems coordinate both, at a cost. Matching the profile to the task is the prerequisite, not the refinement.
1. Reactive Agent - Best for Real-Time, High-Speed Response Work
Reactive agents operate without internal state or memory, responding directly to environmental stimuli through condition-action rules, per the Orchestration of Multi-Agent Systems research (arXiv, 2026). That makes them fast and reliable for single-trigger tasks: auto-tagging an inbound ticket, routing a form submission, firing a Slack alert when a threshold is crossed. The hard limit is equally structural. The moment a task requires context from a prior step, a reactive agent drops the baton.
2. Deliberative Agent - Best for Complex Planning and Multi-Step Reasoning
Deliberative agents maintain an internal world model and use planning mechanisms to sequence actions toward goals, enabling them to own multi-step workflows and adapt when conditions change (arXiv:2601.13671, 2026). This is the profile that can take a brief, break it into ordered sub-tasks, and execute across multiple tools, including those orchestrated through frameworks like LangChain, without waiting for a human checkpoint. The tradeoff is real: reasoning depth costs time. For workflows where a 200ms response window matters more than nuanced judgment, a deliberative agent is the wrong fit.
3. Goal-Based Agent - Best for Outcome-Driven Automation with Flexible Paths
Goal-based agents evaluate actions against a defined end-state rather than fixed rules, giving them the flexibility to reroute when conditions change mid-task. They suit project management automation, dynamic scheduling, and customer journey orchestration where the destination is fixed but the path must adapt. The limitation: they treat all goal-satisfying outcomes as equally acceptable, which fails when quality or cost tradeoffs between paths actually matter.
4. Utility-Based Agent - Best for Optimizing Trade-Offs Across Competing Priorities
Utility-based agents optimize across competing objectives by maximizing an expected utility function, giving them greater flexibility in ambiguous or trade-off-heavy environments (arXiv:2601.13671, 2026). This is the profile for decisions where multiple variables matter simultaneously: cost, speed, and quality cannot all be maximized at once, and the agent must weigh them. The honest tradeoff: defining a utility function that reflects real business priorities is non-trivial, and a poorly specified one produces confident, fast, wrong decisions.
5. Multi-Agent Collaborative System - Best for Enterprise-Scale Parallel Workloads
Multi-agent systems deploy networks of specialized sub-agents that divide tasks, share findings, and synthesize results, ideal for large-scale data pipeline management, enterprise research synthesis, and cross-functional workflow automation where no single agent has sufficient scope. Organizations running parallel, interdependent processes gain the most here. The critical tradeoff is coordination overhead: inter-agent communication introduces latency, failure propagation risk, and significantly higher architectural complexity.
Related Reading
- The Complete Guide to AI Agent Infrastructure & Components
- Make vs n8n: Which Automation Tool Wins in 2026?
- 13 Best Lindy AI Alternatives for Smarter Automation 2026
- Gumloop vs n8n: Which Automation Tool Should You Choose?
- 13 Best AI Agent Builders in 2026
- Multi Agent Orchestration Explained: What It Is and How It Works
AI Agent Use Cases - Where These Capabilities Eliminate the Most Operational Drag
The visible work is rarely where the hours go. It’s the space between systems, the field that needs copying from the email into the CRM, the follow-up no one sent because it lived in a thread that got buried, the onboarding step that stalled because one person forgot to nudge the next. That seam-work is where AI agent workflow automation earns its keep, owning the coordination that currently falls on a human to close.
According to AskElephant (March 2026), sales reps spend 25% of their workweek on manual CRM data entry instead of selling, and separate data from Attention (May 2026) puts total admin time closer to 60% of the week. That is a coordination tax, spread across every handoff point where no single tool claims ownership. The highest-ROI agentic AI use cases sit exactly there: the inter-tool gaps where a human currently acts as the glue.
25% of sales reps’ week lost to CRM entry
One honest friction point worth naming: skepticism about AI agents is reasonable. Broad operational promises have been overstated before, and teams we work with arrive carrying that wariness. The answer is architecture.
Skydive is built multi-teammate by default, meaning coordination is not a feature bolted on later; each teammate runs in its own per-teammate sandbox with browser access, operates across multiple channels, and persists memory between runs. Granular permissions mean a human stays in the loop exactly where the work demands it, and nowhere else. The coordination overhead, the back-and-forth status updates, the “who owns this now?” threads, is what Skydive is designed to remove, so your team stays focused on high-impact work instead of narrating their own progress to each other.
1. Autonomous Lead Qualification - Eliminating the SDR Bottleneck
SDR capacity disappears into prospects that never convert. An AI agent for operations can score inbound leads against your ICP criteria, route qualified contacts forward, and archive the rest without a rep touching the queue. Skydive’s pre-built teammate templates give teams a working qualification layer without starting from scratch, and scheduled runs mean the queue is processed continuously rather than when a rep finds time. The real gain is the compounding recovery of prospecting hours across every cycle, hours that AskElephant documents as currently consumed before a rep ever speaks to a prospect.
The limitation is real: qualification logic is only as good as the criteria you define upfront, so teams with vague ICP definitions will see agents move the wrong leads forward. Skydive’s granular permissions and team collaboration controls let you assign a human reviewer at exactly that definition layer without routing everything else through the same bottleneck.
2. Invoice Processing Automation - Cutting Accounts Payable Cycle Time by 80%
Invoice processing is a chain of low-judgment steps spread across email, accounting software, and approval threads, which makes it a precise match for multi-step AI agent workflow automation. Agents ingest invoices, extract line items, match against purchase orders, and route exceptions to a human reviewer rather than routing everything to one. The structural shift, from routing every invoice through a single reviewer to surfacing only genuine exceptions, is where meaningful cycle time reduction comes from. Skydive’s MCP (Model Context Protocol) support means teammates can connect to the tools already in your finance stack rather than requiring a rip-and-replace, and memory and persistence ensure that an invoice flagged mid-process does not lose its context when the next run fires.
Teams with high invoice variance, custom contracts, irregular vendors, will still need human checkpoints at the exception layer. That is the point: Skydive’s granular permissions let you define exactly where human judgment is required and keep everything else moving autonomously.
3. Client Onboarding Workflow Automation - Removing Repetitive Handoff Friction
Manual onboarding stalls at the same places every time: a welcome email that depends on a form submission someone has to notice, a credentials step waiting on a Slack message that got buried, a kickoff call that cannot be scheduled because the prior step was never marked complete. The back-and-forth communication overhead generated by these gaps is a coordination gap that consumes the kind of focused time Attention documents as already costing teams more than half their week in aggregate.
Skydive coordinates teams through complex, multi-step onboarding workflows without losing track of who owns what at each stage. Multi-channel access means a teammate can act across email, browser, and connected tools in the same sequence, not just send a notification, but complete the next step. Scheduled runs keep onboarding sequences progressing without a human manually advancing each task, and memory and persistence mean the agent retains context from step one through completion rather than treating each trigger as a new event. The result is less time narrating status across threads and more time delivering the onboarding experience the client actually signed up for.
4. AI-Driven Meeting Scheduling - Eliminating Back-and-Forth Email Chains
AI agent capabilities applied to scheduling remove one of the most persistent sources of operational drag in B2B sales: the endless email thread to find a meeting time. Agents parse availability, propose slots, send confirmations, and handle rescheduling autonomously. Ideal for sales teams running high-volume outbound pipelines. The limitation is that complex multi-stakeholder enterprise scheduling with competing time zones still benefits from human coordination oversight.
5. CRM Data Enrichment and Update Automation - Ending Manual Record Hygiene
AI agent capabilities address one of the most universally despised sales tasks: keeping CRM records accurate and current. Agents automatically log call outcomes, enrich contact records with third-party data, update deal stages, and flag stale opportunities for rep review. Best for revenue operations teams managing large pipelines across multiple reps. The tradeoff is that agents can introduce enrichment errors when source data quality from external providers is inconsistent.
Benefits of AI Agents: and the Risks Teams Underestimate Before Deploying
Deploying AI agents without understanding their failure modes is how ops leaders end up with a system that looks fast and produces garbage confidently. The benefits are real and measurable. So are the risks. Both deserve an honest accounting before you commit.
The Four Performance Gains Ops Leaders Actually Measure After Deployment
The gains that show up in practice are specific: reclaimed hours on recurring research and reporting cycles, faster turnaround on cross-tool data synthesis, consistent follow-through on tasks that previously fell into the seams between systems, and judgment that persists across shifts without degrading. Teams report recovering meaningful blocks of calendar time previously consumed by work that required a human to shuttle outputs between platforms. That recovered time is the concrete return ops leaders can bring to a budget conversation.
Why Error Propagation in Autonomous Chains Is the Risk No One Budgets For
Speed is not the same as reliability. According to industry research, errors in autonomous agent chains compound across steps because each action is conditioned on prior outputs. A single hallucination or incorrect tool call early in a pipeline propagates through every subsequent decision before any human sees the result. The failure is invisible until the damage is done.
The actual danger is a plausible but wrong output entering a multi-agent chain and being silently validated by every downstream agent acting on it. The reliability of your agent system is determined not by any single agent’s accuracy, but by the quality of observable checkpoints between steps.
Where Human-in-the-Loop Remains Non-Negotiable
The same December 2024 research is direct on this: fully autonomous end-to-end ownership is reliable only for well-scoped, lower-stakes tasks where the action space and success criteria are clearly defined. Ambiguous decision points, high-stakes outputs, and anything touching live financial or customer data still require a human checkpoint. The cost of a compounding error in those contexts outweighs the efficiency gain of removing the review step.
How to Put AI Agent Capabilities to Work - Without Rebuilding How Your Team Operates
The seams between your tools are where hours disappear, and where the risk surface enterprise teams are now scrambling to contain actually lives. A request lands in Slack, gets actioned in your CRM, needs a follow-up in email, and somewhere in that chain, a human becomes the manual connector. The question is whether fixing it requires a six-month project, or just a decision.
The Highest-Leverage Deployment - Coordinated Agents at the Seams
A single capable agent handles tasks. A coordinated set owns the transitions between them. According to industry research, the real unlock of AI agents is a network that hands work across tools and teams without a human bottleneck at every step. The ops work that consumes the most time is rarely the work itself; it is the moving of outputs from one system to the next.
How to Deploy AI Agents Without Engineering Support - Describing Work in Plain Language
The assumption that AI agent deployment requires engineering support has quietly become outdated. Agents can now be configured from plain-language descriptions rather than visual workflow builders or custom code. An ops lead who builds an AI Employee in an afternoon by describing the work in plain language, then connecting it to Slack and a CRM, stops being the manual handoff between those two systems. That is a description, not a rebuild.
Why Judgment Codification, Not Tooling, Is the Real Bottleneck to AI Agent Deployment. The hidden cost of single-agent or chatbot deployments is continuity.
Related Reading
- Lindy vs Zapier: Which Automation Tool Wins in 2026?
- 13 Best Relevance AI Alternatives for Building AI Agents 2026
- How to Master AI Agent Prompt Engineering in 2026
- 15 Best Gumloop Alternatives for AI Automation in 2026
- How to Build a Multi Agent Workflow That Actually Scales
- Types of AI Agent Pricing Models (And How to Choose)
Next steps
If your team is still acting as the manual connector between tools, closing the loop between a Slack message, a CRM update, and an email follow-up by hand, the path forward starts with recognizing that the bottleneck is not your tooling. It is judgment codification: translating the operating logic currently held by a person into persistent infrastructure that runs without waiting for that person to advance each step.
Two insights make the next action obvious. First, the six capabilities that define a real agent (perception, memory, tool use, planning, multi-step execution, and inter-agent handoff) are not additive features of a chatbot but an entirely different architectural class. Missing even one of them means the system cannot own a workflow, only comment on it. Second, the highest-ROI deployment opportunities sit precisely at the inter-tool handoff points where a human currently acts as the glue, with sales and ops teams losing 25 to 60 percent of their week to admin work that no single tool has claimed ownership of. Together, those two realities point to one action: deploy agents that are architected to own those seams, not just respond inside them.
Start with AI Employees to see how Skydive’s coordinated teammate architecture handles the handoffs your team is currently closing by hand. From there, each teammate can be configured in plain language, connected to the tools already in your stack, and running on a schedule before the week is out.
Frequently Asked Questions
What are the key components that make up a true AI agent architecture?
A true AI agent requires three non-negotiable components: perception (reading inputs from text, APIs, and environmental signals), memory (retaining context within and across sessions), and tool use (reaching into external systems to take action). Wrap those layers around an LLM and you have an agent; remove any one of them and you have a very articulate chatbot.
What is the difference between a reactive agent and a deliberative agent, and when should I use each?
Reactive agents have no internal memory or state and respond directly to a single trigger, making them fast and reliable for tasks like auto-tagging a ticket or routing a form submission, but they drop the baton the moment a task requires context from a prior step. Deliberative agents maintain an internal world model and can plan across multiple steps and tools without waiting for a human checkpoint, though that reasoning depth costs time, making them the wrong fit when a sub-200ms response window matters more than nuanced judgment.
What is a utility-based agent and what kind of work is it suited for?
Utility-based agents optimize across competing objectives by maximizing an expected utility function, giving them greater flexibility in ambiguous or trade-off-heavy environments. This profile is designed for decisions where multiple variables, such as cost, speed, and other priorities, must be weighed simultaneously rather than handled one at a time.
Why do most AI agent pilots fail before they deliver real value?
The root cause is a definitional mismatch: teams deploy conversational AI expecting autonomous task ownership and receive reactive Q&A instead. Industry data cited by Fortune in August 2025 found that 95% of generative AI pilots at companies are failing, with misaligned expectations about what the tool category can actually do identified as a documented root cause.
Why isn’t a powerful LLM alone enough to act as an AI agent?
An LLM alone cannot observe what’s happening in your systems, retain what happened in a prior session, or interact with any external tool, it processes text you hand it and generates a response, but nothing actually moves. As Menlo Ventures noted in their 2025 State of Generative AI in the Enterprise report, the agentic layer wraps around LLMs specifically to give them perception, memory, and tool use, and removing any one of those layers leaves you with a capable reasoning engine that cannot own real work end to end.