Agentic Assistant Tools That Actually Work for You in 2026
Ops leaders, an agentic assistant closes the follow-through gap so you stop re-entering the loop and finally get a day back.
 Skydive 25 min read
Table of contents
Your AI assistant isn’t underperforming because the model is weak. It’s underperforming because it was built to answer, not to finish. Here’s the architectural gap that actually explains the difference.
The common assumption is that AI assistants are getting better fast enough that the follow-through gap will close on its own, and that the next model upgrade will finally get the work off my plate. That experience is not a failure of patience or prompting skill. It is a failure of definition.
What most teams deployed was a reactive tool built to answer questions. What they needed was something built to own outcomes. Understanding that gap is the first step toward actually closing it.
A traditional AI assistant responds. You prompt it; it replies; the conversation ends. An agentic assistant does something categorically different: it holds a goal across time, selects the tools it needs, executes actions, and keeps going after the conversation window closes.
According to Gartner’s 2026 Hype Cycle for Agentic AI, agentic AI systems are designed to understand high-level goals, plan multi-step execution, and act autonomously, going beyond answering questions to taking actions and orchestrating complex workflows without continuous human direction. That last phrase is the operative one. No continuous human direction.
Reactive tools are useful the way a search engine is useful. They return information when asked. But a Head of Operations does not need better answers. She needs the task finished, the follow-up sent, and the status updated, without re-entering the loop after each step.
Gartner draws this line explicitly: traditional AI tools “respond only to explicit prompts rather than proactively pursuing objectives.” That architecture is the ceiling. You can upgrade the model, sharpen the prompt, and add more integrations, and a reactive tool will still stop the moment the conversation ends. Gartner’s analysis found that this conflation “has led to widespread disappointment with AI ROI.”
Autonomous end-to-end execution means the Agentic Assistant reads the context, plans the steps, calls the tools it needs, and checks its own output before surfacing a result. It is a completed task. The distinction is structural, not incremental. Six criteria define this model:
- Whether the system holds a goal across time rather than closing after each prompt
- Whether it selects and calls tools autonomously without per-step human direction
- Whether it executes actions end-to-end rather than returning instructions for a human to act on
- Whether it checks its own output before surfacing a result
- Whether it is architected around a persistent perception-reasoning-action loop rather than a conversation window
- Whether it closes the follow-through gap in ways reactive tools structurally cannot
Key takeaways
- An agentic assistant isn’t a smarter chatbot, it’s an AI that holds judgment, context, and follow-through across tools and time, without you re-entering the thread after every step.
- The gap between a traditional AI assistant and an agentic one isn’t measured in response quality, it’s measured in whether the work actually finishes after the conversation ends.
- Three structural capabilities define a real agentic assistant: goal-oriented planning, autonomous tool use, and multi-step memory. Remove any one and the other two just return unfinished work to your plate.
- Knowledge workers lose an average of 2.5 hours per day to email management alone, agentic AI targets that cost at the structural level, not the convenience layer.
- Multi-agent systems, where specialized agents each own a defined function under one orchestration layer, are how enterprise teams scale agentic work beyond what a single assistant can hold.
- The reason agentic tools fail inside existing stacks isn’t model capability, it’s adoption architecture. The tools that close the follow-through gap in 2026 live where teams already work.
- SkyDive closes that architecture gap by letting teams build AI teammates that handle real work inside Slack, email, iMessage, and web chat, no new interface to adopt, no thread to hold.
How Agentic Assistants Differ from Traditional AI Assistants: the Comparison That Actually Counts
The common assumption among heads of operations is that AI assistants are getting better fast enough that the follow-through gap will close on its own, that the next model upgrade will finally get the work off their plate. But the gap between a traditional AI assistant and an agentic one is measured in what happens the moment the conversation window closes.
If you’ve trialed a chatbot for operations work, you already know the feeling. You get a sharp, well-structured answer. Then you open four other tabs to act on it.
The AI handed you a better to-do list, not a finished task.
That’s the core failure mode: you stop trialing tools that don’t stick precisely because they return suggestions, not output. According to the Speakwise Team (Knowledge Worker Productivity Statistics 2026), the productivity gap for knowledge workers is an architecture problem: current AI tools return the work to the operator’s plate after generating a response, because they lack the multi-step, tool-integrated, goal-directed architecture that defines agentic systems.
That architectural difference plays out across four specific axes. Understanding them is the difference between buying a smarter assistant and buying a fundamentally different kind of infrastructure.
Four Axes Where the Architectures Actually Diverge
| Axis | Traditional AI Assistant | Agentic Assistant |
|---|---|---|
| Response Style | Returns a suggestion or draft; conversation ends | Returns an action taken; task continues until resolved |
| Workflow Scope | Single prompt, single output | Multi-step sequences across time and context |
| Tool Use | Describes what to do in another tool | Executes directly inside connected tools and systems |
| Autonomy | Reactive; waits for the next prompt | Proactive; monitors, escalates, and follows up without re-prompting |
The table is about who owns the work after the first exchange.
There’s a second failure mode that surfaces for operations teams running sensitive or technically complex workflows: traditional AI assistants built on commercial API-based models are blocked from legitimate analysis by guardrails that cannot distinguish an incident responder from an attacker, or a compliance reviewer from a bad actor. The result is that the tool refuses exactly the work you need it to do. Agentic, self-hosted setups, with granular permissions and per-teammate sandboxes, remove that ceiling by letting you define the trust boundary yourself, rather than inheriting one designed for the lowest-common-denominator public user.
The Follow-Through Gap - Why Chatbots Produce Suggestions While Agentic Assistants Produce Outcomes
Consider a vendor follow-up. A traditional AI assistant drafts the email. You send it. You remember to check for a reply. You decide whether to escalate. You update the record. Every one of those steps sits back on your plate the moment the chat closes. An agentic assistant, one built with scheduled runs, memory and persistence, and direct tool execution, sends the email, monitors the inbox, escalates if the vendor hasn’t replied in 48 hours, and updates the relevant record without being re-prompted. That is what it means to get real output from AI tools, not suggestions.
The architecture that makes this possible isn’t a single capability; it’s a stack. SkyDive is multi-teammate by default, meaning discrete teammates can own discrete workflow stages and hand off between each other with full context intact. Each teammate operates in its own per-teammate sandbox where it can run code & commands, read & write files, browse the web, search the web, host web apps, process media, and give itself new tools as needed, so work that spans tools doesn’t require you to become the engineer connecting them.
Anyone on the team creates teammates. Permissions control view, use, or edit on a per-teammate basis. Useful teammates spread the way useful things inside companies always spread.
Memory and persistence mean context doesn’t reset between sessions. A teammate that started a vendor negotiation on Monday still knows where it stands on Thursday.
That isn’t a smarter model. That’s a different owner.
The Speakwise Team (Knowledge Worker Productivity Statistics) notes that knowledge workers face up to 275 interruptions per day, each one compounding the cost of context-switching across disconnected tools. The Journal of Work-Applied Management frames this structurally: knowledge worker productivity degrades not from lack of effort but from the overhead of coordination, status updates, handoff checks, and re-prompting cycles that consume the hours that should go to high-impact work. Coordinating a team through complex, multi-step workflows without losing track of who owns what at each stage, and reducing the back-and-forth communication overhead so the team stays focused rather than chasing status, are outcomes an architectural shift produces. A model upgrade cannot.
275 daily interruptions for knowledge workers
How Agentic AI Works - The Perception-Reasoning-Action Loop Explained
The mechanism that keeps judgment alive between triggers runs on a four-stage cycle: perception, reasoning, action, and learning. Every agentic assistant that sustains progress across a multi-step task without human re-entry does so by moving through these stages continuously, each pass informing the next, until the outcome exists.
“Agentic AI loops running uninterrupted (e.g. 30+ minutes) produce worse code quality compared to shorter, more human-in-the-loop sessions, the perception-reasoning-action loop, when left unchecked, degrades output.”
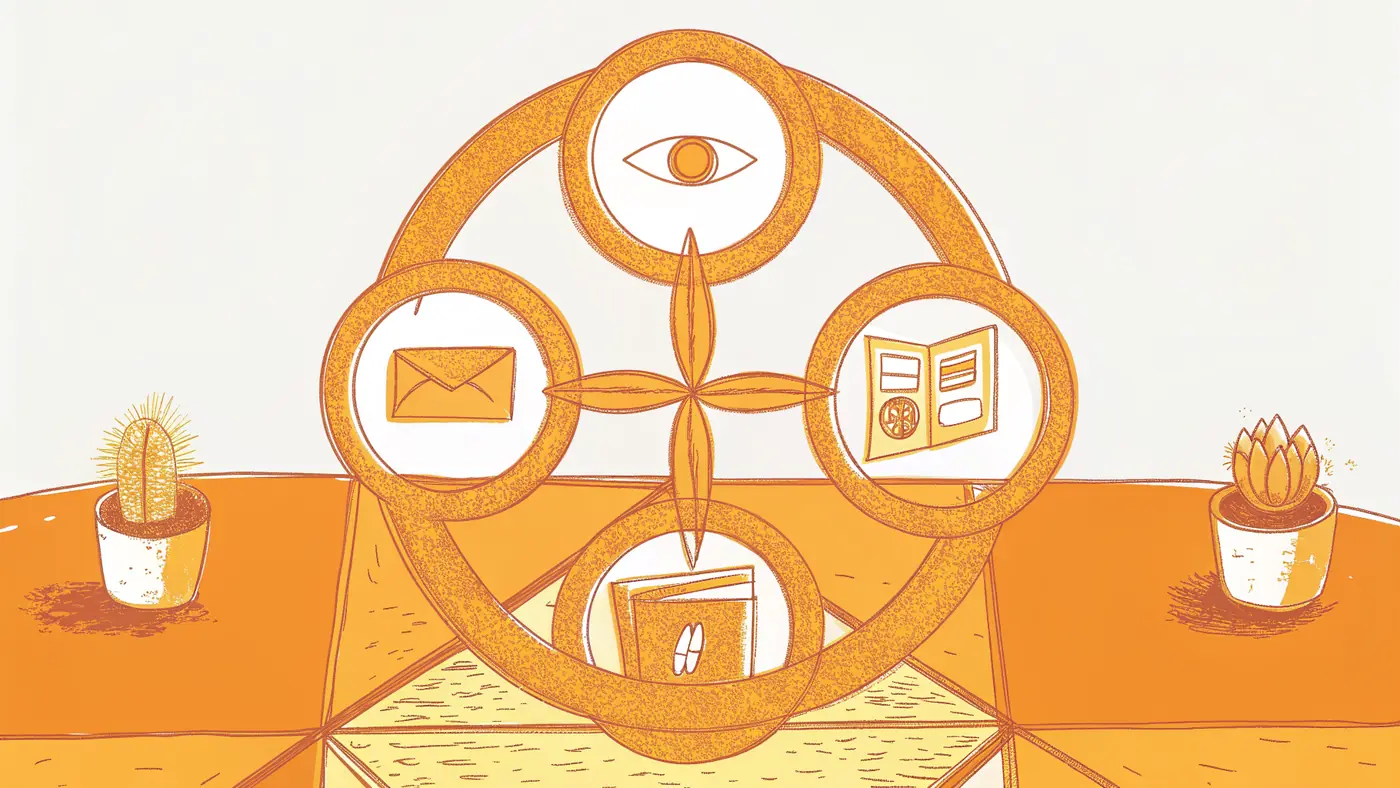
Across the market, agentic AI operates through a continuous loop: perception (reading context and inputs), reasoning (planning the next action), action (executing via tools or integrations), and reflection (reviewing intermediate results to catch errors before moving forward). That sequence is the engine. Each stage feeds directly into the next, so the system is always mid-task rather than waiting for a new prompt.
Take a concrete example: an agentic assistant assigned to onboard a new vendor. It reads the intake form (perception), maps the steps needed to get that vendor into the payment system (reasoning), emails the vendor and updates the tracker (action), then checks whether the vendor responded and re-queues the follow-up if they haven’t (reflection). The work continues.
The thread stays inside the system. In SkyDive, that entire thread is owned by a dedicated teammate with its own sandboxed environment that can run code and commands, read and write files, browse and search the web, host web apps, and process media, and give itself new tools as needed, so the context the teammate built during perception is still intact when reflection kicks in, without anyone manually re-injecting it.
Why Self-Reflection Mid-Task Is the Feature That Separates Agentic Assistants from One-Shot Automations
Most automations are brittle. They execute a fixed sequence and stop, whether the output is correct or not. Self-reflection changes that. What most teams report bears this out: the reflection stage lets an agent review intermediate results, identify mistakes, and adjust strategy mid-task rather than committing to a single output and handing the mess back to you.
This is the architectural reason agentic AI is categorically different from a chatbot. A chatbot breaks after the action step: it produces an output, returns it to you, and waits. An agentic assistant loops. It catches its own errors before they compound.
Pros and cons at a glance
| ✓ Pros | ✗ Cons |
|---|---|
| Self-reflection lets agent review intermediate results mid-task | Loops left unchecked produce degraded output quality over time |
| Catches its own errors before they compound | Compounds small errors rather than correcting them past a certain duration |
| Categorically different from brittle one-shot automations | Running loops at scale carries meaningful compute cost |
| Transforms a capable response into a completed outcome | Unchecked autonomy can become unsustainable for everyday workflows |
There is, however, a real ceiling on how long that loop should run unchecked. Teams we work with have seen it directly: agentic loops left running without a human checkpoint produce noticeably degraded output quality compared to shorter, structured cycles. The perception-reasoning-action loop doesn’t improve indefinitely on its own; past a certain duration it compounds small errors rather than correcting them.
Running loops at scale also carries meaningful compute cost, and unchecked autonomy can become genuinely unsustainable for everyday workflows. That reality shapes how SkyDive is built. Scheduled runs and granular permissions mean your team defines when each teammate acts and how far its authority extends, so the loop stays productive rather than drifting.
The most effective deployments are structured, with deliberate review points built in.
That self-correcting capability, applied within a well-defined boundary, transforms a capable response into a completed outcome. It also frees your team from the coordination overhead that would otherwise consume the hours best spent on strategic marketing judgment, positioning work, and the high-impact decisions that require a human in the chair.
The Loop Doesn’t Stop When the Conversation Does
A common assumption is that the agent is dormant between exchanges. In practice, the loop re-enters itself at the next trigger: an incoming email, a Slack message, a scheduled check-in. The judgment doesn’t evaporate. It persists inside the architecture.
Every time the loop breaks without that persistence, the Head of Ops becomes the re-entry point, manually re-injecting context the system should have carried forward, burning exactly the calendar time that should be protected for strategic judgment work. SkyDive’s memory and persistence layer is built to prevent that tax. Teammates retain context across sessions, re-enter at the next trigger, and hand off inside a multi-teammate structure with clear ownership at each stage, so your team can see who owns what without a status-update meeting to find out. As broader industry trends make clear, the reflection pattern is only durable when the system can carry forward what it learned, not start cold every time a new message arrives.
The Three Capabilities That Make an Agentic Assistant Actually Useful
Three capabilities separate an agentic assistant from a faster way to generate more to-do items for yourself. Three structural requirements, where the absence of any one collapses the other two into something that still returns unfinished work to your plate.
The critical insight, easy to miss: goal-oriented planning, autonomous tool use, and multi-step memory are not independent upgrades. They form a single interdependent system. Without persistent memory, planning restarts from scratch every session. Without tool use, reasoning produces text instead of action. Without planning, tool calls become a series of disconnected API requests with no throughline. Incrementally adding one capability at a time does not close the follow-through gap. All three must be present simultaneously for the system to own an outcome end-to-end.
1. Multi-Step Autonomous Planning - Executing Complex Tasks Without Hand-Holding
Goal-oriented planning is the capacity to break a large objective into sequential, manageable steps without requiring step-by-step human prompts. Across the market, agentic assistants use this capability to pursue multi-stage goals autonomously, which directly addresses fragmented task ownership: the operator states the outcome, not the method. This is what it means to make a CEO’s leverage persistent. The judgment and priorities they bring to high-stakes decisions stop living only in their head and start being encoded into the system that executes on their behalf.
The real tradeoff is compounding error risk. Longer task chains mean more decision points where a flawed intermediate step quietly corrupts every step downstream, so planning capability is most valuable when paired with mid-task error review rather than treated as a set-and-forget mechanism. SkyDive’s scheduled runs address this directly: tasks can be structured to check back at defined intervals rather than running to completion in a single unreviewed pass, so a Head of Operations coordinating complex, multi-step workflows doesn’t lose visibility into who owns what at each stage.
2. Persistent Memory Across Sessions - Retaining Context That Makes Assistance Personal
Multi-step memory is the capability that solves the judgment-walks-out-the-door problem. Broader industry trends make clear that this allows an agentic assistant to retain context over extended operations, track completed work, troubleshoot errors mid-task, and adjust strategy without restarting from scratch. Anyone who has re-explained their team’s priorities to an AI tool at the start of every session knows exactly what the absence of this capability costs. It keeps the operator as the one holding the thread between sessions.
This is the direct mechanism for making judgment persistent so it doesn’t walk out the door. A senior operator’s institutional knowledge, the context that shapes every decision, should accumulate inside the system rather than evaporate between conversations. SkyDive’s memory and persistence layer is built for exactly this: context that was relevant on Monday is still present and active on Friday, across teammates, across channels, across handoffs. The pattern holds at scale: knowledge worker productivity losses compound fastest at the handoff points where context is lost, not during the execution work itself.
Persistent memory is most beneficial when the work spans days or involves multiple handoffs, which describes most of what a Head of Operations actually owns. It is also the foundation for work that requires multi-step reasoning over time: planning high-impact team offsites, managing multi-phase projects, or coordinating anything where the full picture only becomes visible across sessions. SkyDive’s multi-teammate architecture means that memory is not siloed to a single agent; it travels with the task across the team of teammates assigned to it, so no single handoff becomes a context cliff.
These three capabilities are powerful enough when a single agentic assistant deploys them. But operations work rarely fits inside one agent’s scope. When a task spans research, communication, and execution simultaneously, the architecture has to scale beyond one agent entirely, which is where the next layer of agentic design comes in.
3. Dynamic Tool Calling - Reaching Outside the Model to Act on the Real World
Autonomous tool use means the assistant can access external environments, databases, software integrations, and APIs to execute actions, not just generate text about them. What most teams report is that this is what moves an agentic system from producing suggestions to performing work inside connected systems. A practical example: using LangChain, an agentic assistant can chain a CRM lookup into an email draft, send it, and log the result without a human touching the thread between steps. The infrastructure layer making this possible, including LangChain, AutoGen, and Model Context Protocol (MCP), wires planning and memory into functioning agentic systems.
Work that lives in the seams between tools, research in one place, communication in another, execution in a third, stops fragmenting when tool calling spans all three in a single task. SkyDive’s MCP support is one concrete implementation of this: agents carry context across connected systems rather than treating each tool boundary as a hard stop. Combined with per-teammate sandboxes that include browser access and multi-channel reach, this means a SkyDive teammate can move across the full surface area of a task, from lookup to outreach to logging, without handing the thread back to a human at each transition. Back-and-forth communication overhead shrinks because the status-update loops that existed only because no single system could previously hold the full thread are gone.
SkyDive’s granular permissions and team collaboration layer sits on top of this tool-calling infrastructure, so the same capability that gives teammates broad reach across connected systems also gives operators precise control over what each teammate can touch. Broad access and tight governance are both present by design.
Related Reading
- How to Measure AI Agent ROI Before You Scale
- The Future of Agentic AI For Customer Support Explained
- 13 Best Agentic AI Platforms in 2026 for Autonomous Work
- 13 Best AI Agent Integrations to Automate More in 2026
- 14 Best Browser Use Agent Tools for AI Web Automation 2026
- The Ultimate AI Automation Tutorial for Beginners (2026)
- AI Agent vs Assistant: Key Differences Compared (2026)
- How To Measure AI Agent ROI With Proven Metrics
- What Are Parallel AI Agents? A Complete 2026 Guide
- 13 Best AI Agents for Marketing Teams in 2026
- How to Set AI Agent Permissions Without Losing Control
Multi-Agent Collaboration and Enterprise Agentic AI - When One Agent Isn’t Enough
Multi-agent collaboration is a system architecture in which multiple specialized AI agents each own a defined function, coordinated by a single orchestration layer that routes work between them. Each agent is scoped to what it does well: one pulls data, one drafts, one schedules, one executes. The orchestrator reads the incoming task, decomposes it, and delegates, without a human deciding who gets what.
This mirrors how actual operations teams are structured. Research doesn’t happen in the same motion as stakeholder communication, and neither happens in the same motion as execution. A multi-agent architecture that reflects that division is the structural match for how the work already flows.
The dramatic projected growth in enterprise agentic AI adoption, from under 5% to 40% of applications in a single year, is being driven by a structural insight that model upgrades cannot supply: complex cross-functional work requires multiple specialized agents, not a single increasingly capable one. Because real operations are already divided across teams and functions, a multi-agent architecture that mirrors that division is the baseline design required for AI to do work that matches how the organization actually runs.
Why the Single-Agent Ceiling Hits Operations Teams First and Hardest
Operations is the function where work crosses the most boundaries. A single request from a founder can require pulling competitive data, drafting a brief, updating a tracker, and booking a review, all before lunch. A single agent handles those tasks serially. The queue builds. The bottleneck is throughput.
The frustration teams report is consistent: latency and coordination overhead make single-agent setups impractical for high-frequency, cross-functional work. The model is not the constraint. The architecture is. Organizations still waiting for one powerful general-purpose model to handle cross-functional tasks are waiting for an architecture that enterprise practitioners have already abandoned.
Orchestrator vs. Specialist - The Two Roles Every Enterprise Multi-Agent System Needs
Every functioning multi-agent system needs exactly two things: an orchestrator that decomposes goals and routes tasks, and specialist agents that execute within a defined scope. According to industry research, enterprise-scale agentic AI relies on this pattern because complex cross-functional tasks cannot be handled by a single generalist without serializing work that should run in parallel.
The orchestrator holds the map.
Agentic AI for Personal Productivity and Why ‘Personal Assistant’ Undersells It
The “personal assistant” label sticks because the time savings are real and easy to see, but it quietly caps what you expect from the technology before you have explored what it can actually do. What separates a genuinely agentic assistant from a smarter inbox tool is the perception-action loop: the ability to read context, act, check the result, and keep moving without being re-prompted at every step. That distinction changes not just how much work gets done, but who carries the judgment behind it.
What Agentic Assistants Actually Deliver Beyond Personal Productivity
Knowledge workers lose an average of 2.5 hours per day to email management alone. That figure explains why AI scheduling assistants and inbox tools land so well: the pain is immediate, the time savings are visible, and the win is easy to demo. Tools positioned at personal productivity, calendar coordination, meeting prep, and research synthesis genuinely deliver on that promise.
But here is the honest trade-off: if you stop at personal productivity, you have automated relief for one person. The judgment behind those decisions still lives only in that person’s head.
Why the Perception-Action Loop Changes What Delegation Means
The reason agentic AI feels different from earlier automation is the loop. The agent reads context, plans a next action, executes it, checks the result, and adjusts, without you re-prompting between steps. That continuity is what makes it feel like delegation rather than drafting.
The frustration teams consistently hit is that most tools break the loop when the conversation window closes. Context resets. The next session starts from zero. That overhead erodes the time you thought you saved.
Why ‘Personal Assistant’ Is the Wrong Frame for an Agentic Assistant
Here is what most productivity comparisons miss: framing an agentic assistant as a “personal assistant” undersells it in precisely the way that matters most, because a personal assistant relieves one person of effort, while an agentic assistant removes the structural bottleneck that makes effort accumulate in the first place. The constraint was never time or intelligence; it was always the absence of a system that owns task continuity across tools and time without the worker holding the thread.
The same loop architecture that books your calendar can carry institutional judgment across a team restructure. That second capability is the one that matters to an operations leader whose knowledge keeps walking out the door every time someone leaves or a role changes. Workers who face up to 275 interruptions per day don’t have a focus problem that another calendar block will fix; they have a return-to-sender loop that fragments output regardless of how much bandwidth any individual reclaims.
What Makes an Agentic Assistant Tool Actually Work Inside Your Stack in 2026
Most agentic assistant tools fail inside real stacks not because the underlying model is weak, but because the architecture demands that people change how and where they work. That distinction matters for anyone evaluating AI platforms right now, because it shifts the question from which tool scores highest on benchmarks to which tool actually embeds where your team already operates. What follows breaks down why integration architecture is the variable that determines whether an agentic assistant closes work or just adds another system to maintain.
Why Integration Architecture Beats Model Capability
The core insight most AI procurement decisions miss is this: the reason agentic assistant tools fail to deliver real work inside an existing stack is an adoption architecture problem that model upgrades cannot fix. The tools that will close the follow-through gap are the ones that embed inside the communication channels where work already happens and can be configured by an operations leader without engineering effort.
Buying the most capable AI platform feels like the obvious move. The trap is that capability without native integration relocates fragmentation to a parallel system your team has to remember to open, populate, and maintain alongside everything else.
Why Platform Migration Is the Failure Mode, Not the Onboarding Step
According to the OpenAI State of Enterprise AI 2025 Report, only 1% of companies describe themselves as mature in AI deployment. The bottleneck isn’t model intelligence. What most teams report, again and again, is that the primary barrier is the expectation that employees must migrate to new tools rather than AI integrating into systems where work already happens. Deployments stall before they deliver anything, not because the AI was wrong, but because the architecture demanded too much change from the people it was supposed to help.
The Hidden Cost of Canvas-Based Workflow Builders - You Become the Engineer
Operations leaders often report spending weeks inside visual workflow builders before a single automation runs. Across the market, the pattern is consistent: when non-technical leaders are required to act as workflow architects to deploy AI tools, they are shifted out of their strategic role entirely. The tool promised to free the Head of Operations. Instead, it handed them a new job title they never wanted.
Related Reading
- What Is Agentic AI for Business Operations and Why It Matters
- 12 Best AI Automation for Sales Tools That Actually Work
- 13 Best AI Automation Software Tools I Tested in 2026
- 18 Best AI Agent Platform Comparison Tools for 2026
- 13 Top AI Automation Tools I Tested and Ranked for 2026
- How Much Does an AI Agent Cost? 2026 Pricing Breakdown
- Zapier AI Agent: Build and Automate Smarter Workflows
- AI Agent Framework Comparison: Top Picks Ranked for 2026
- 15 Best Agentic Automation Tools to Try in 2026
- Gumloop vs Zapier: Which Tool Wins for AI Automation?
- RPA vs AI Agents: Which Automation Wins in 2026?
Next steps
If your day keeps fragmenting across half-finished handoffs and tools that return suggestions instead of outcomes, the path forward starts with recognizing that the gap is architectural, not incremental. Model upgrades improve answers. They do not change who owns execution after the conversation ends. Start with our AI teammates.
The perception-reasoning-action-reflection loop is what separates a completed outcome from a better to-do list. Without it, the thread returns to your plate every time. And goal-oriented planning, autonomous tool use, and persistent memory are not three independent upgrades you can add one at a time. Remove any one of them and the system collapses back into something that still requires you to hold the context, re-inject it the next session, and manually connect the seams between tools. Together, they point to a single practical question: does the tool you are evaluating own the thread after the conversation closes, or does it hand that responsibility back to you?
From there, you can map which workflows in your current stack still have you as the return address, and identify where a teammate with persistent memory, direct tool execution, and multi-step planning would close that loop without requiring you to become the engineer who builds it.
Frequently Asked Questions
What’s the real difference between a reactive AI assistant and an agentic one?
A reactive AI assistant stops the moment the conversation ends, it returns a suggestion and waits for your next prompt. An agentic assistant holds a goal across time, selects the tools it needs, executes actions, and keeps going without continuous human direction, meaning the work actually gets finished rather than handed back to you.
Why do AI tools keep returning work to my plate even after I get a great-sounding answer?
That’s an architecture problem, not a model-quality problem. Traditional AI tools are built around a conversation window that closes after each response, so every follow-up step, sending the email, checking for a reply, updating the record, lands back on you. Agentic systems are built around a persistent perception-reasoning-action loop that keeps executing until the outcome exists.
How does an agentic assistant avoid compounding its own mistakes over a long task?
The reflection stage of the perception-reasoning-action loop lets the agent review intermediate results and adjust strategy mid-task before errors compound downstream. That said, this guide is clear that loops left running unchecked too long do degrade in output quality, which is why structured review points and scheduled runs, rather than fully unchecked autonomy, produce the most reliable results.
Do goal-oriented planning, tool use, and memory each work on their own, or do I need all three at once?
All three must be present simultaneously, they form a single interdependent system. Without persistent memory, planning restarts from scratch every session. Without tool use, reasoning produces text instead of action. Without planning, tool calls become disconnected API requests with no throughline. Adding them one at a time does not close the follow-through gap.
Does the agentic assistant go dormant between conversations, or does it actually keep running?
It re-enters the loop at the next trigger, an incoming email, a Slack message, or a scheduled check-in, rather than going dormant. Memory and persistence mean the context built during earlier stages is still intact when the agent picks back up, so your team isn’t manually re-injecting context every time a new message arrives.