13 Types of AI Agents in the Workplace Shaping 2026
Ops leaders, learn which AI agents in the workplace actually cut coordination overhead so the seam work stops landing back on you.
 Skydive 29 min read
Table of contents
One AI agent makes one task faster. It does nothing for the handoffs, the context gaps, and the coordination tax that still lands on you. Here is what each agent type actually owns, and why the seams between them are the real problem.
Most heads of operations assume that adding one AI agent to the stack will reduce the coordination overhead and get cross-functional work off their plate. What they get instead is a faster way to answer isolated questions, while the actual work, the handoffs, the context-passing, the cross-tool execution, stays exactly where it was: on a person.
“Companies are reluctant to grant AI agents real data access due to deep concerns about security leaks and data exposure in workplace environments.”
That gap is structural. Understanding why starts with a clear definition of what an AI agent actually is, and an honest look at what even the best single agent cannot do. See our AI teammates for how this works in practice.
A chatbot responds. A workflow rule triggers. An AI agent does something categorically different: it perceives its environment, reasons about a goal, and selects among multiple possible action paths to reach it. Agents are also distinguished from rule-based automation by their ability to handle ambiguous goals and adapt mid-task. Three properties separate a true agent from everything else: it reads context, it plans a sequence of steps, and it acts across tools rather than inside one chat window. Remove any one of those and you have a smarter search bar, not an autonomous AI agent.
The agent loop is what makes workplace automation feel different in practice. An agent reads a trigger, plans the steps required to resolve it, executes across the relevant tools, checks its own output, and loops back if something is off. No prompt required for each step.
Consider the difference between a Slack-connected tool that answers HR policy questions and an agent that reads the new-hire form, creates the Notion page, sends the welcome email, and pings the manager without being asked twice. The second one is running a loop. The first one is waiting.
A single agent can own a discrete function well. What it cannot do is manage the handoff to the next function, because that requires context from a system it does not sit inside or a shared trigger it was never designed to receive, and that gap is precisely where the coordination overhead lands back on a person.
Key takeaways
- One AI agent in the workplace speeds up one task and leaves every handoff, context-pass, and cross-tool dependency exactly where it was, on a person.
- The structural break isn’t a feature gap in any single agent; it’s the seam between agents where work gets dropped and ops leaders absorb the cost.
- Naming an agent by department (HR, IT, sales) tells you almost nothing about what triggers it, which systems it touches mid-task, or what it passes downstream.
- 42% of businesses scrapped most of their AI initiatives in 2025, not because the technology failed, but because teams assumed agents required fully mapped workflows and engineering queues before they could own anything.
- Governance isn’t a compliance layer you add after deployment; the real risk is scope, access, and institutional logic accumulating quietly until something breaks or a key person leaves.
- The companies pulling measurable results from AI agents in 2026 didn’t win on tooling, they won on coordination, deploying agents that hand off work the way a reliable employee does.
- SkyDive closes that coordination gap by letting teams build AI teammates that handle real work inside Slack, email, iMessage, and web chat, no engineering queue required to get started.
Where Single-Agent Deployments Break Down and Where the Real Work Gets Dropped
Automation promised to give the Head of Operations their time back. The common assumption is that adding one AI agent to the stack will reduce the coordination overhead and get cross-functional work off their plate. In practice, deploying a single AI agent tends to move one task faster while leaving everything around it exactly as fragmented as before.
The Task Gets Done Faster, The Seam Work Still Lands on You
A scheduling agent books the meeting. A support agent closes the ticket. The bounded, visible task gets handled. But the moment that task touches another system, another team, or a decision that requires context from three different threads, the agent stops. Someone has to pick it up. That someone is almost always you.
*Key takeaway: According to the Asana Anatomy of Work Index (2022), workers spend 60% of their time on work about work, status checks, information searches, app-switching, and unclear ownership.*
60% of work time spent on work about work
Automating one task in that system does not touch the coordination layer. It just makes one node slightly faster while the seams between nodes stay exactly where they were.
Three Friction Points a Single Agent Cannot Cross, Context, Coordination, and Institutional Memory
Consider a research request that starts in Slack, pulls from Google Drive, references a CRM record, and needs a drafted response in email. A single agent owns one of those surfaces. The other three require a human to carry the context forward manually. That handoff cost is invisible on any roadmap, but it lands somewhere real every single day.
Context loss across tools is structural, not accidental. Employees switch between apps an average of 25 times per day, per the same Asana research. Each switch is a seam where information drops. One agent operating inside one tool cannot close seams it was never designed to reach.
25 app switches per employee per day
The Coordination Tax Operations Leaders Pay for Agent Handoff Gaps
The agent cannot remember what was decided last Tuesday. It cannot hand a task to the finance team without a human writing the bridge message. It has no memory of prior decisions, no visibility into the adjacent system, and no mechanism to initiate a handoff on its own, which means every cross-functional transition still defaults to the Head of Operations as the human router.
13 Types of AI Agents in the Workplace and the Work Each One Actually Owns
Vendor brochures love a clean grid: HR agent, sales agent, IT agent, support agent. Neat columns, tidy rows, and the implicit promise that naming the category is the same as understanding what the thing actually does. A label tells you the department. It tells you almost nothing about what triggers the work, which systems the agent touches mid-task, or what it passes to the next person, human or otherwise, when it’s done.
That gap matters more than most teams realize. Workers already spend roughly that same share of their time chasing information, duplicating effort, and context-switching between tools, rather than on the skilled work itself. An agent that carries a department label but has no defined trigger, no action loop, and no handoff isn’t reducing that overhead. It answers questions at the edge of the problem while the real drag runs underneath.
The more useful frame is functional: what does each agent type actually own, where does its work begin, and what does it hand off when it’s done? That’s the lens applied to every entry below. Think of this list less as a taxonomy and more as a functional org chart, where each role has a clear job description rather than a job title.
1. Scheduling & Calendar Agent - Owns Every Meeting Coordination Task
Scheduling agents autonomously find open slots, send invites, handle rescheduling, and resolve conflicts across time zones without human back-and-forth. They’re the right pick for operations teams and executive assistants drowning in calendar chaos. The real tradeoff: they struggle with nuanced prioritization, knowing which meeting actually matters more than another still requires human judgment.
2. Customer Support Agent - Owns Tier-1 Ticket Resolution at Scale
The cost difference between a human agent resolving a Tier-1 ticket and an autonomous agent resolving the same ticket is significant, and at volume it compounds fast. This agent type handles incoming support requests, classifies them, pulls from a knowledge base, resolves what it can, and escalates what it can’t, with full context passed forward rather than forcing the customer to repeat themselves. In SkyDive, each support teammate operates inside its own per-teammate sandbox with browser access, meaning it can verify live account data or look up current product documentation mid-resolution rather than relying solely on a static knowledge base snapshot.
Most beneficial when ticket volume is high and a large share of requests are genuinely repetitive. The limitation: it needs a well-maintained knowledge base to draw from; point it at stale documentation and it confidently delivers wrong answers.
3. Enterprise Search Agent - Owns Knowledge Retrieval Across Siloed Systems
The failure mode this agent addresses is familiar. Someone needs a contract, a policy document, or a past decision, and spends 20 minutes pinging three people across two tools before finding it or giving up. The Enterprise Search Agent connects to the systems where knowledge actually lives (Google Drive, Confluence, Notion, SharePoint, email archives) and returns a single answer rather than a list of places to look.
SkyDive’s ability to run code & commands, read & write files, browse the web, search the web, host web apps, and process media, and to give itself new tools as needed, means this agent can reach across the full stack of connected tools without custom integration work for each system. Most valuable in organizations where institutional knowledge is spread across more than three platforms. The tradeoff is access: it can only surface what it’s been given permission to index, so anyone on the team creates teammates.
Permissions control view, use, or edit on a per-teammate basis. Useful teammates spread the way useful things inside companies always spread.
4. Knowledge Management Agent - Owns Documentation Freshness and Institutional Memory
Documentation goes stale faster than most teams want to admit. A process written in Q1 is often wrong by Q3, but no one flags it until a new hire follows it and something breaks. According to Deel (2025), HR automation tools can autonomously handle multi-step processes without human intervention at each step, and the same logic applies here: a Knowledge Management Agent monitors documents for age, cross-references them against current workflows, flags outdated content, and can draft updated versions for human review.
SkyDive’s memory and persistence layer means the agent retains context across sessions, so it isn’t re-scanning the same document library from scratch each time it runs, but building on what it already knows about which sections have changed and which haven’t. Best for mid-size teams where documentation ownership is genuinely unclear. The real limitation is that it can identify staleness but cannot always determine whether a change in process was intentional or accidental without human confirmation.
5. Autonomous Coding Agent - Owns Feature Development and Bug-Fix Cycles
This agent type operates at the level of a junior-to-mid developer: it takes a defined task (fix this bug, write a test for this function, scaffold this component), executes it against the codebase, and opens a pull request for review. It doesn’t replace senior engineering judgment, but it removes the queue of small, well-specified tasks that slow senior engineers down, preserving their time for the architecture and positioning decisions that require real expertise. SkyDive’s per-teammate sandbox with browser means the coding agent can reference live documentation, dependency changelogs, or error logs mid-task rather than working from a frozen context.
Most beneficial when the engineering backlog contains a high ratio of clearly scoped, lower-complexity work. The tradeoff is specificity: vague task descriptions produce vague code, and the agent has no way to ask clarifying questions unless that loop is explicitly built in.
6. Business Intelligence Agent - Owns Data Analysis and Automated Insight Delivery
A common pattern in operations teams is that the data exists, the dashboards exist, and the insights still don’t arrive until someone manually pulls a report and interprets it. The Business Intelligence Agent closes that gap by monitoring data sources, running scheduled analyses, and pushing summaries to the right channel without being asked. SkyDive’s scheduled runs capability handles the trigger automatically; no one needs to remember to kick off the Monday morning report.
That said, one failure mode teams consistently encounter with AI agents doing analytical or reporting work is numerical error. When the underlying data is inconsistent, poorly structured, or sourced from misaligned systems, these agents produce figures that look authoritative but are wrong, leading to inaccurate evaluations of employees, products, or business performance. It is a predictable failure when the data infrastructure is not clean.
SkyDive’s team collaboration and granular permissions controls let you configure exactly which data sources each BI agent can touch, reducing the risk of an agent quietly pulling from a stale or mismatched dataset. Most beneficial when the organization already has reliable data infrastructure. For teams still reconciling data across spreadsheets, this is not the right first deployment.
7. Sales Outreach Agent - Owns Prospecting, Sequencing, and Follow-Up Cadences
Sales reps spend a documented share of their week on tasks that aren’t selling: researching prospects, writing sequence emails, logging calls in the CRM, and following up on threads that went quiet. The Sales Outreach Agent handles that layer. It researches a target account, drafts a personalized outreach sequence, sends it across the configured channels, logs responses, and flags the accounts that warrant a human conversation.
SkyDive’s multi-channel access means the agent operates across Slack, email, iMessage, and web chat, the channels where outreach and follow-up actually live, rather than being confined to a single inbox. Best for teams running outbound at volume where the bottleneck is throughput, not relationship depth. The limitation is nuance: for enterprise deals where a single misread of tone can cost the relationship, human review of outreach before it sends is worth the extra step.
8. HR Operations Agent - Owns Onboarding Workflows and Employee Request Handling
According to Deel (2025), HR automation can reduce time spent on administrative tasks by up to 40%, and the mechanism is straightforward: the HR Operations Agent handles the repetitive transactional requests that consume HR staff capacity. A new hire triggers an onboarding sequence. An employee asks about their PTO balance.
A manager requests a policy document. The agent handles each without a ticket being filed or a human being interrupted. SkyDive integrates directly into existing workplace tools, Slack, email, HRIS systems, so the trigger-to-resolution loop happens in the same channel where the request originated, with no context lost in transit.
9. Contact Center Voice Agent - Owns Inbound Call Handling and Live Resolution
Voice agents handle inbound calls in natural language, authenticate callers, resolve common issues, and escalate to human agents with full context when needed, all in real time. They’re the right fit for enterprise contact centers where call volume spikes are unpredictable and hold times damage CSAT scores. The tradeoff is accent and dialect variability, speech recognition accuracy still degrades meaningfully with non-standard speech patterns.
10. Compliance Monitoring Agent - Owns Regulatory Risk Detection Across Communications
Compliance agents continuously scan emails, documents, contracts, and communications for regulatory violations, flagging risks before they become incidents and generating audit-ready reports automatically. They’re essential for financial services, healthcare, and legal teams operating under strict regulatory frameworks. The limitation is false-positive fatigue, overly sensitive models generate alert noise that can cause compliance teams to deprioritize genuine risks.
11. Procurement Agent - Owns Vendor Sourcing, Quote Comparison, and PO Generation
Procurement agents autonomously identify vendors, request quotes, compare pricing against historical benchmarks, and generate purchase orders within pre-approved spend thresholds. They’re the right pick for operations and finance teams looking to compress procurement cycle times without adding headcount. The tradeoff is relationship nuance, preferred vendor agreements and strategic partnerships require human oversight that pure cost-optimization logic will override.
12. Marketing Content Agent - Owns Campaign Copy, SEO Briefs, and Content Publishing
Marketing content agents draft blog posts, ad copy, email campaigns, and social content based on briefs, then schedule and publish across channels autonomously. They’re ideal for lean marketing teams that need to maintain publishing velocity without a large content team. The critical limitation is brand voice drift, without rigorous style guide enforcement and human review cycles, output quality and tone consistency degrade over time.
13. IT Helpdesk Agent - Owns L1 Support Tickets, Password Resets, and System Provisioning
IT helpdesk agents resolve common employee requests, password resets, software access, VPN troubleshooting, device provisioning, autonomously by integrating directly with identity management and ITSM platforms. They’re the right fit for IT teams where L1 tickets consume the majority of engineer time that should be spent on infrastructure and security work. The tradeoff is scope creep risk, without clear escalation boundaries, agents attempt complex fixes they’re not equipped to handle safely.
Multi-Agent Systems and Orchestration - How These 13 Types Work as a Coordinated Team
The seam between agents is where the work dies. You can deploy a support agent, a CRM agent, and a comms agent on the same afternoon, and by Monday morning you’re still the one copying outputs from one tool into the next, because nothing told them to talk to each other. That gap is what keeps cross-functional work landing on the Head of Operations personally.
What Multi-Agent Orchestration Actually Means (Beyond the Buzzword)
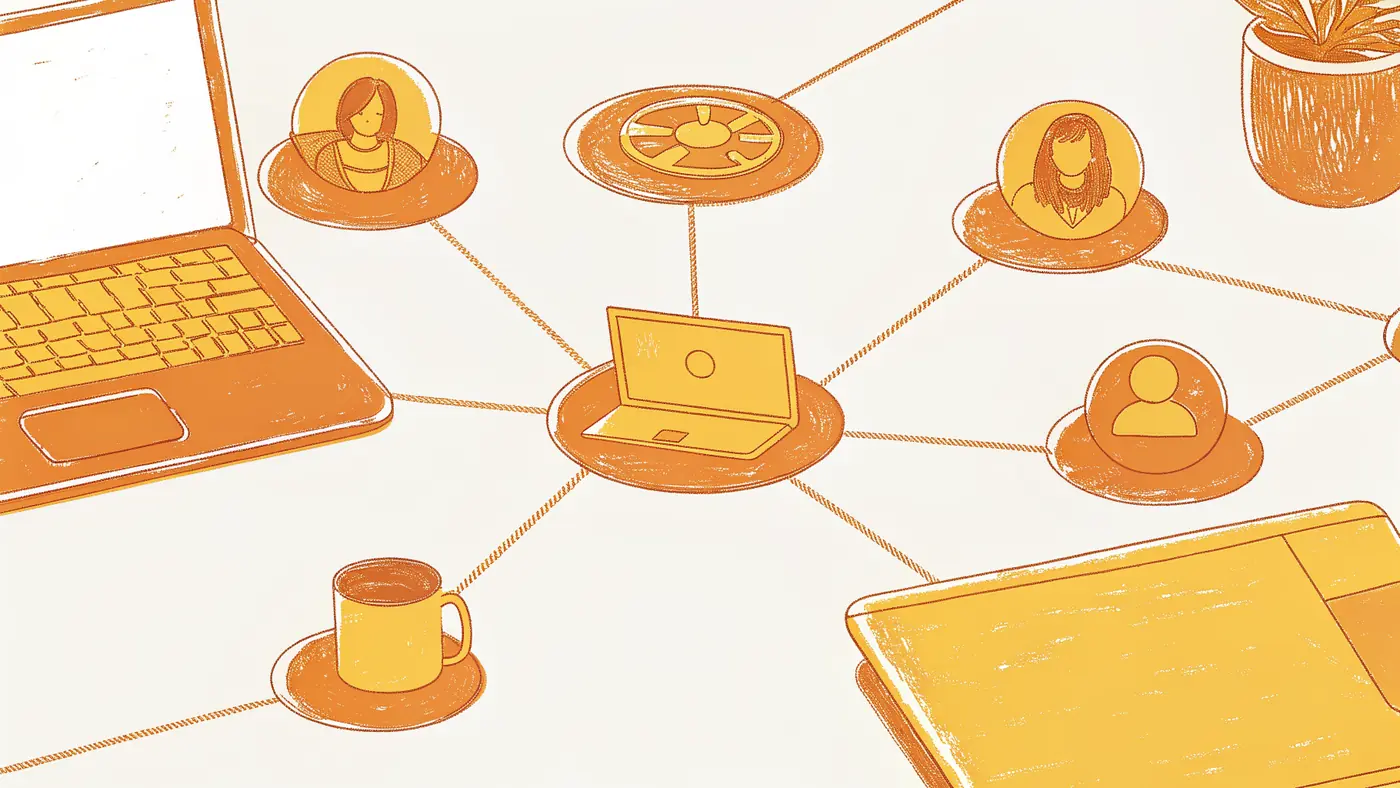
Multi-agent orchestration is the routing logic that lets specialist agents hand work to each other without a human in the middle. An orchestrator agent decomposes a complex task, routes subtasks to specialized agents, then reassembles their outputs into a final result, enabling end-to-end automation of cross-functional workflows without human handoffs. That last phrase is the operative one.
Orchestration isn’t a feature you toggle on; it’s the organizational logic that determines whether your agents form a team or a pile. But here is what most implementation guides skip: multi-agent orchestration only delivers on its coordination promise when each specialist agent has unambiguous ownership of a distinct function, because without clear ownership boundaries, the orchestrator routes tasks correctly yet creates a new class of human overhead, someone who must constantly adjudicate which agent is responsible when mandates overlap.
The Orchestrator Agent - How It Routes Tasks, Delegates to Specialist Agents, and Reassembles Results
Think of the orchestrator agent as the chief of staff who never sleeps and never loses track of a thread. It receives a trigger, breaks the work into subtasks, assigns each to the right specialist, and waits for outputs before assembling a coherent result. The orchestrator does not do the specialist work itself. A single generalist agent trying to research, draft, update, and send all at once runs into context limits and priority conflicts. The orchestrator delegates precisely because separation of function is what makes the system reliable.
How Specialist AI Agents Receive, Execute, and Hand Off Work
Each specialist agent has a defined input format, a defined scope of action, and a defined output it passes forward. When the orchestrator routes a task, the receiving agent doesn’t need to interpret intent from scratch; the context travels with the handoff. This is the architectural detail that separates a system that scales from one that breaks the moment a workflow gets complex.
The handoff is also where failure typically surfaces in production. Teams running multi-agent systems report that when context doesn’t transfer cleanly, agents either duplicate work or stall waiting for information they were never given. Clean handoffs require that each agent’s output is structured well enough for the receiving agent to act on without interpretation, which is why defining output format at the point of agent creation, before the first failure, is the highest-leverage architectural decision in a multi-agent deployment.
Related Reading
- The Future of Agentic AI For Customer Support Explained
- 13 Best Agentic AI Platforms in 2026 for Autonomous Work
- How to Measure AI Agent ROI Before You Scale
- 13 Best AI Agent Integrations to Automate More in 2026
- AI Agent vs Assistant: Key Differences Compared (2026)
- How To Measure AI Agent ROI With Proven Metrics
- The Ultimate AI Automation Tutorial for Beginners (2026)
- 14 Best Browser Use Agent Tools for AI Web Automation 2026
- 13 Best AI Agents for Marketing Teams in 2026
- How to Set AI Agent Permissions Without Losing Control
- What Are Parallel AI Agents? A Complete 2026 Guide
Real-World Company Examples of AI Agents at Work in 2026
Forget the Fortune 500 transformation story. The most instructive AI agent deployments in 2026 are happening inside 30-person teams, operations functions, and mid-market companies where the work lives in Slack threads and shared inboxes, not SAP implementations. Here is what case studies rarely surface explicitly: the companies pulling measurable results from AI agents didn’t win on agent sophistication; they won by eliminating the behavior-change requirement for the humans around the agent. They deployed agents inside the tools teams already use rather than asking employees to adopt a new interface, and that integration point is precisely why adoption held where other deployments failed, especially given that the majority of AI initiatives were scrapped, most of them bolted onto workflows as chat windows that left coordination burden unchanged.
According to Moveworks, 350+ leading enterprises rely on AI agents to handle workplace requests autonomously, with common IT and HR requests, including password resets, policy lookups, and access provisioning, resolved before they ever reach a human agent. The behavior-change requirement was eliminated. The agent came to the employee, not the other way around.
1. SkyDive - Best for Teams That Want AI Teammates, Not Just Chatbots
A strong fit when a team needs more than one function covered and wants multi-agent handoffs to happen inside channels they already use, rather than managing the coordination cost of stitching separate point tools together. AI teammates lets operators describe a full bench of agents in plain language and deploy them inside existing channels, so a Research agent hands off to a Proposal agent, hands off to a CRM agent, without a human routing in between. The real tradeoff: it’s built for 15-50 person teams, so if you need enterprise-grade compliance infrastructure on day one, the fit isn’t there yet.
2. Moveworks - Best for Enterprise HR and IT Service Automation at Scale
Moveworks earns its place on any shortlist for large organizations where IT and HR ticket volume is the primary drag. Moveworks’ agents are designed to autonomously understand, plan, execute, and adapt to complete any request end-to-end across IT, HR, finance, and other enterprise functions, including requests that fall outside well-defined and repeatable patterns. The limitation worth naming: Moveworks is purpose-built for service-desk contexts. Cross-functional work that spans ops, comms, and finance still requires additional tooling.
3. Automation Anywhere - Best for AI Agents in Manufacturing and Supply Chain Operations
 Automation Anywhere is the right consideration for operations teams in manufacturing or supply chain contexts where agents need to interact with physical-process data, ERP systems, and production-floor triggers. Its strength is RPA-native orchestration, robotic process automation layered with AI judgment, which gives it an advantage in environments where legacy systems don’t expose clean APIs. The honest tradeoff: the platform is built for structured, high-volume transactional environments, and teams running knowledge-work coordination in Slack and Google Workspace will find the setup overhead exceeds the benefit.
4. Kore.ai - Best for Healthcare Organizations Deploying Patient-Facing AI Agents
 Kore.ai specializes in deploying AI agents across healthcare settings, handling appointment scheduling, patient intake, clinical workflow support, and administrative cost reduction at scale. It’s the right choice for health systems that need compliant, conversational agents with proven real-world deployment examples. The tradeoff is that its healthcare-specific depth means less flexibility for teams outside regulated verticals who want a general-purpose agent platform.
5. Tulip - Best for Frontline Manufacturing Teams Needing Advisory AI Agents with Human Guardrails
Tulip takes a deliberate, human-in-the-loop approach to AI agents on the shop floor, surfacing recommendations and guidance to frontline workers rather than acting fully autonomously. It’s the right pick for manufacturers who want AI augmentation without ceding control of high-stakes production decisions. The tradeoff is intentional: teams seeking fully autonomous agent execution will find Tulip’s guardrail-first philosophy a constraint rather than a feature.
AI Agent Governance and Oversight - How to Keep a Team of Agents Running Without Losing Control
Treating AI agent governance as a compliance layer you add after deployment is the operational equivalent of installing smoke detectors after the fire. The real cost is the quiet accumulation of scope, access, and institutional logic that lives nowhere formal until the moment something breaks or a key person walks out.
Why Autonomous Action Across Tools Makes Governance Non-Negotiable
Agents that operate across tools, systems, and functions aren’t just running tasks. They’re making access decisions continuously. 97% of AI-related breaches stem from access control failures, not from model errors or adversarial attacks. That single figure reframes the entire governance conversation: this is an ownership-boundary problem that must be solved at the point of agent definition, not patched afterward.
The Thomson Reuters Institute found a significant gap between AI policy and practice: companies may have governance frameworks on paper but lack the operational controls and audit mechanisms to enforce them. In a multi-agent system, that gap compounds. Each agent added without defined scope boundaries multiplies accountability gaps faster than it reduces coordination overhead.
This is a pressure teams feel acutely in practice. When agents are multi-teammate by default, coordinating across functions, channels, and workflows simultaneously, the question of who owns what at each stage becomes urgent. SkyDive is built around that reality: granular permissions and team collaboration controls are native to the platform, not retrofitted. Every teammate operates inside a per-teammate sandbox with defined access boundaries, so the permission layer is established at creation, before an agent ever touches a live workflow.
The Three Permission Layers Every Agent Deployment Needs
Every agent operating across functions needs three things defined before it touches a live workflow:
- What it can access
- Who or what can trigger it
- A complete log of what it actually did
Access without initiation controls means any connected system can invoke the agent. Initiation without audit trails means no one can reconstruct why a decision was made. All three layers work together, or none of them hold.
A practical example: a Finance Agent scoped to read transaction data and generate reports should be administratively blocked from initiating transfers. That boundary isn’t enforced by asking the agent nicely. It’s encoded in the permission layer at creation. SkyDive’s granular permissions architecture makes this concrete: access scope is defined at the teammate level, not assumed, so teams can coordinate complex, multi-step workflows without losing track of who owns what at each stage. MCP (Model Context Protocol) support extends this discipline to external tool connections, ensuring that integrated capabilities inherit the same boundary logic rather than bypassing it.
The downstream benefit is equally operational: because teammates can automate follow-throughs without losing context, the overhead that typically forces teams into constant status-update cycles is absorbed by the agent layer rather than the human layer.
Audit Trails as Institutional Memory
Logged agent actions are the organizational memory that survives turnover. When an agent executes a task, updates a record, or initiates a handoff, that action should be timestamped, attributed, and stored in a format a human can reconstruct. This matters most at the moment it’s least expected: when a process breaks, when a team member leaves, or when an auditor asks why a decision was made six months ago.
The Thomson Reuters Institute finding cuts to the core of why this is structurally necessary: governance frameworks that exist on paper but lack operational audit mechanisms fail precisely at the moments they’re needed most. SkyDive’s memory and persistence layer addresses this directly: agent actions, context, and handoffs persist across runs, so the record of what happened and why isn’t locked inside a single session or a single person’s working memory. Scheduled runs generate consistent, attributable activity logs by design, meaning the audit trail builds automatically rather than requiring a dedicated engineer to reconstruct it after the fact.
The audit trail is the institutional record that keeps a multi-agent system accountable without requiring constant human supervision. In a platform built multi-teammate by default, that accountability infrastructure is what makes autonomous action across tools governable at scale.
Related Reading
- What Is Agentic AI for Business Operations and Why It Matters
- 12 Best AI Automation for Sales Tools That Actually Work
- 13 Best AI Automation Software Tools I Tested in 2026
- 18 Best AI Agent Platform Comparison Tools for 2026
- 13 Top AI Automation Tools I Tested and Ranked for 2026
- How Much Does an AI Agent Cost? 2026 Pricing Breakdown
- Zapier AI Agent: Build and Automate Smarter Workflows
- AI Agent Framework Comparison: Top Picks Ranked for 2026
- 15 Best Agentic Automation Tools to Try in 2026
- Gumloop vs Zapier: Which Tool Wins for AI Automation?
- RPA vs AI Agents: Which Automation Wins in 2026?
How to Start Deploying AI Agents in Your Workplace Without Becoming the Engineer
The engineering-first assumption is costing ops teams more than time. According to S&P Global Market Intelligence, 42% of businesses scrapped most of their AI initiatives in 2025, and the most common culprit wasn’t the technology. It was the belief that agents require fully mapped workflows, integration tickets, and an engineering queue before they can own anything real.
Find the Function With the Most Orphaned Cross-Tool Work First
The highest-leverage starting point is a friction audit. The practical first move is identifying the single cross-functional handoff where the most orphaned work lives. That’s the function where tasks fall between tools, ownership is unclear, and the Head of Operations ends up as the default fallback. Start there, not with the process that’s easiest to document.
Describe the Agent’s Job in Plain Language, Not a Workflow Diagram
Once you’ve found the friction point, the next move is ownership-first description. No process map, no API spec. A plain statement of what the agent is responsible for, what it can initiate, and when it hands off. Industry research frames this directly: description-first, not process-first is what separates teams that deploy in days from teams that stall for months.
Worth naming the trade-off honestly: this approach works best when the function has clear ownership boundaries. Before deploying, confirm the following:
- Identify the single cross-functional handoff where the most orphaned work lives
- Confirm that a human today could answer “who owns this?”; if not, resolve that accountability question before deploying
- Write a plain-language statement of what the agent is responsible for, what it can initiate, and when it hands off
- Deploy the agent into that cleared lane, not into genuinely ambiguous shared territory
If the work is genuinely ambiguous across multiple teams, where no single person today could answer “who owns this?”, deploying an agent before resolving that ownership question will replicate the ambiguity at speed. Clarify the human accountabilities first, then describe the agent’s job in plain language and deploy into that cleared lane.
Next steps
If your cross-functional work keeps landing back on one person because agents answer questions but never own a handoff, the path forward starts with deploying a coordinated bench of specialists rather than a single generalist tool.
The 60% coordination tax insight makes the priority clear: the overhead killing your team’s capacity isn’t located inside any one task, it lives in the seams between tasks, and a single agent deployed at one node leaves every seam intact. The ownership-first orchestration insight makes the sequence clear: agents that share overlapping mandates create a new class of human adjudication work, which means the first architectural decision isn’t which agent to add but which function each agent will own without ambiguity. Together, those two realities point toward building a defined bench of specialist agents with clean handoffs rather than stacking point tools and hoping coordination improves by proximity.
Start by seeing AI teammates for the full range of specialist teammates available today. From there, apply the friction-first sequence from the deployment section: find the one cross-functional handoff where the most orphaned work currently lives, describe that agent’s ownership in plain language, and deploy it inside the channel your team already uses. The second agent’s job gets easier because the first one closed a real seam.
Frequently Asked Questions
What’s the actual difference between an AI agent and a chatbot?
A chatbot responds to prompts, but an AI agent perceives its environment, reasons about a goal, and selects among multiple possible action paths to reach it. The key distinction is the agent loop: an agent reads a trigger, plans the steps required to resolve it, executes across relevant tools, checks its own output, and loops back if something is off, no prompt required for each step.
If I deploy one AI agent, why is coordination work still landing on me?
A single agent can own a discrete, bounded task well, but it cannot manage the handoff to the next function because that requires context from a system it doesn’t sit inside or a shared trigger it was never designed to receive. According to the Asana Anatomy of Work Index, workers already spend 60% of their time on work about work, status checks, information searches, and unclear ownership, and automating one task doesn’t touch that coordination layer.
What can an AI agent actually do for customer support?
A Customer Support Agent handles incoming requests, classifies them, pulls from a knowledge base, resolves what it can, and escalates what it can’t, with full context passed forward so the customer doesn’t have to repeat themselves. It’s most beneficial when ticket volume is high and a large share of requests are genuinely repetitive, though it needs a well-maintained knowledge base to draw from, since pointing it at stale documentation leads to confidently delivered wrong answers.
How can AI agents help with HR tasks like onboarding?
An HR Operations Agent handles repetitive transactional requests, triggering a new-hire onboarding sequence, answering PTO balance questions, or surfacing a policy document, without a ticket being filed or a human being interrupted. Deel’s 2025 research indicates HR automation can reduce time spent on administrative tasks by up to 40%, and the trigger-to-resolution loop can happen in the same channel where the request originated, with no context lost in transit.
What does an AI coding agent actually handle and what does it leave for senior engineers?
An Autonomous Coding Agent operates at the level of a junior-to-mid developer: it takes a well-defined task, fixing a bug, writing a test, scaffolding a component, executes it against the codebase, and opens a pull request for review. It doesn’t replace senior engineering judgment; instead, it removes the queue of small, clearly scoped tasks that slow senior engineers down, preserving their time for architecture and positioning decisions that require real expertise.